H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
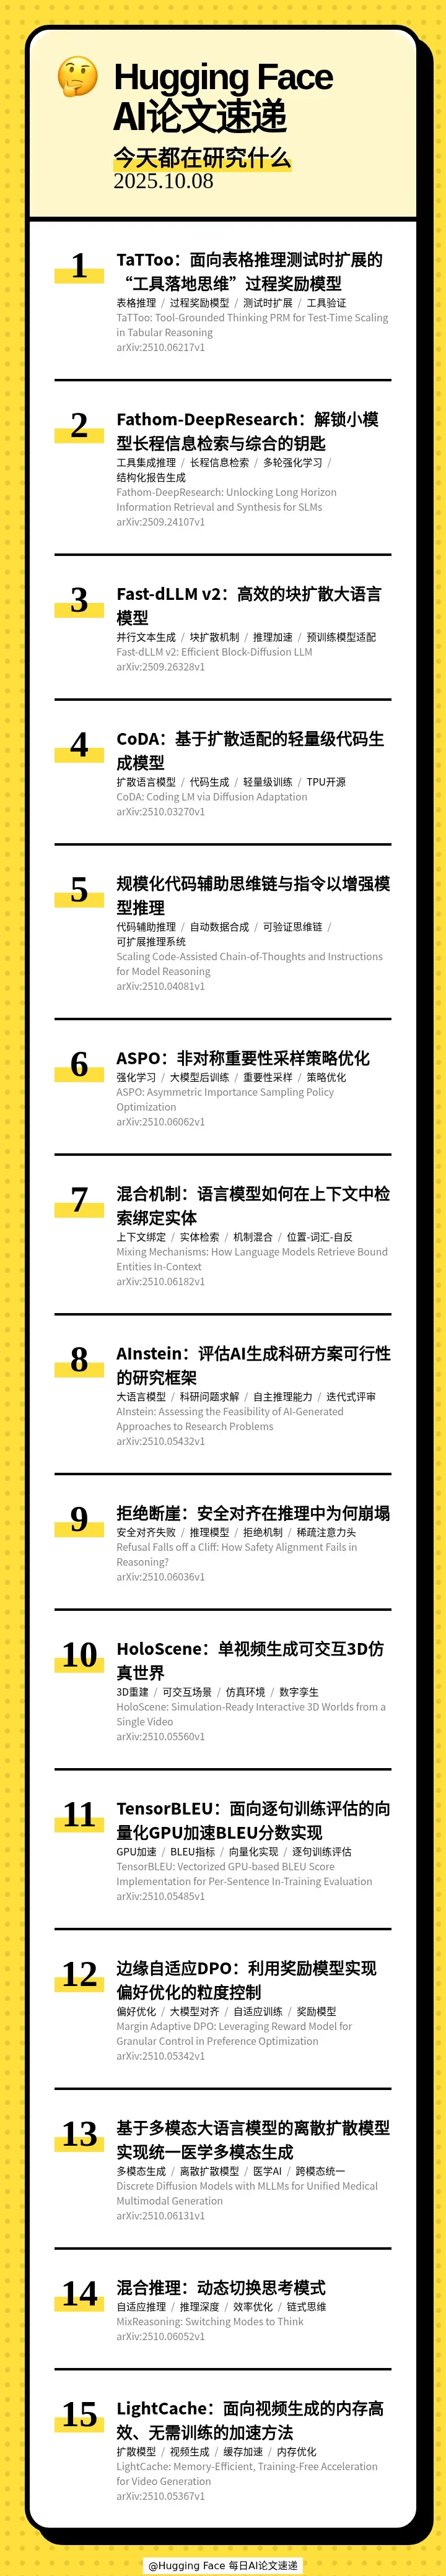
[] 📊 TaTToo: Tool-Grounded Thinking PRM for Test-Time Scaling in Tabular Reasoning(TaTToo:面向表格推理测试时扩展的“工具落地思维”过程奖励模型)
[] 🔍 Fathom-DeepResearch: Unlocking Long Horizon Information Retrieval and Synthesis for SLMs(Fathom-DeepResearch:解锁小模型长程信息检索与综合的钥匙)
[] 🚀 Fast-dLLM v2: Efficient Block-Diffusion LLM(Fast-dLLM v2:高效的块扩散大语言模型)
[] 🧑 CoDA: Coding LM via Diffusion Adaptation(CoDA:基于扩散适配的轻量级代码生成模型)
[] 🧩 Scaling Code-Assisted Chain-of-Thoughts and Instructions for Model Reasoning(规模化代码辅助思维链与指令以增强模型推理)
[] ⚖ ASPO: Asymmetric Importance Sampling Policy Optimization(ASPO:非对称重要性采样策略优化)
[] 🔗 Mixing Mechanisms: How Language Models Retrieve Bound Entities In-Context(混合机制:语言模型如何在上下文中检索绑定实体)
[] 🧠 AInstein: Assessing the Feasibility of AI-Generated Approaches to Research Problems(AInstein:评估AI生成科研方案可行性的研究框架)
[] 🪂 Refusal Falls off a Cliff: How Safety Alignment Fails in Reasoning?(拒绝断崖:安全对齐在推理中为何崩塌)
[] 🌍 HoloScene: Simulation-Ready Interactive 3D Worlds from a Single Video(HoloScene:单视频生成可交互3D仿真世界)
[] ⚡ TensorBLEU: Vectorized GPU-based BLEU Score Implementation for Per-Sentence In-Training Evaluation(TensorBLEU:面向逐句训练评估的向量化GPU加速BLEU分数实现)
[] 🎯 Margin Adaptive DPO: Leveraging Reward Model for Granular Control in Preference Optimization(边缘自适应DPO:利用奖励模型实现偏好优化的粒度控制)
[] 🩺 Discrete Diffusion Models with MLLMs for Unified Medical Multimodal Generation(基于多模态大语言模型的离散扩散模型实现统一医学多模态生成)
[] 🧠 MixReasoning: Switching Modes to Think(混合推理:动态切换思考模式)
[] ⚡ LightCache: Memory-Efficient, Training-Free Acceleration for Video Generation(LightCache:面向视频生成的内存高效、无需训练的加速方法)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 10 月 9 日 · 11 分钟
本期的 15 篇论文如下:
[] 📊 TaTToo: Tool-Grounded Thinking PRM for Test-Time Scaling in Tabular Reasoning(TaTToo:面向表格推理测试时扩展的“工具落地思维”过程奖励模型)
[] 🔍 Fathom-DeepResearch: Unlocking Long Horizon Information Retrieval and Synthesis for SLMs(Fathom-DeepResearch:解锁小模型长程信息检索与综合的钥匙)
[] 🚀 Fast-dLLM v2: Efficient Block-Diffusion LLM(Fast-dLLM v2:高效的块扩散大语言模型)
[] 🧑 CoDA: Coding LM via Diffusion Adaptation(CoDA:基于扩散适配的轻量级代码生成模型)
[] 🧩 Scaling Code-Assisted Chain-of-Thoughts and Instructions for Model Reasoning(规模化代码辅助思维链与指令以增强模型推理)
[] ⚖ ASPO: Asymmetric Importance Sampling Policy Optimization(ASPO:非对称重要性采样策略优化)
[] 🔗 Mixing Mechanisms: How Language Models Retrieve Bound Entities In-Context(混合机制:语言模型如何在上下文中检索绑定实体)
[] 🧠 AInstein: Assessing the Feasibility of AI-Generated Approaches to Research Problems(AInstein:评估AI生成科研方案可行性的研究框架)
[] 🪂 Refusal Falls off a Cliff: How Safety Alignment Fails in Reasoning?(拒绝断崖:安全对齐在推理中为何崩塌)
[] 🌍 HoloScene: Simulation-Ready Interactive 3D Worlds from a Single Video(HoloScene:单视频生成可交互3D仿真世界)
[] ⚡ TensorBLEU: Vectorized GPU-based BLEU Score Implementation for Per-Sentence In-Training Evaluation(TensorBLEU:面向逐句训练评估的向量化GPU加速BLEU分数实现)
[] 🎯 Margin Adaptive DPO: Leveraging Reward Model for Granular Control in Preference Optimization(边缘自适应DPO:利用奖励模型实现偏好优化的粒度控制)
[] 🩺 Discrete Diffusion Models with MLLMs for Unified Medical Multimodal Generation(基于多模态大语言模型的离散扩散模型实现统一医学多模态生成)
[] 🧠 MixReasoning: Switching Modes to Think(混合推理:动态切换思考模式)
[] ⚡ LightCache: Memory-Efficient, Training-Free Acceleration for Video Generation(LightCache:面向视频生成的内存高效、无需训练的加速方法)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟