H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

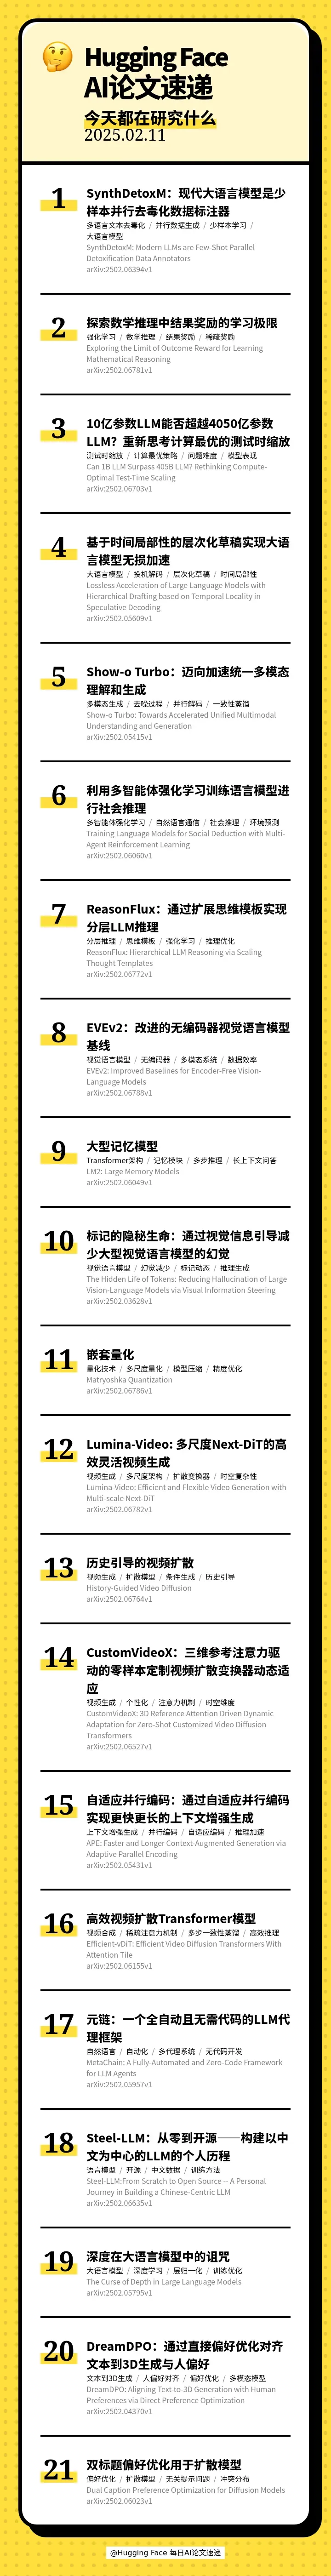
本期的 21 篇论文如下:
[] 🤖 SynthDetoxM: Modern LLMs are Few-Shot Parallel Detoxification Data Annotators(SynthDetoxM:现代大语言模型是少样本并行去毒化数据标注器)
[] 🧠 Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning(探索数学推理中结果奖励的学习极限)
[] 🤔 Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling(10亿参数LLM能否超越4050亿参数LLM?重新思考计算最优的测试时缩放)
[] ⚡ Lossless Acceleration of Large Language Models with Hierarchical Drafting based on Temporal Locality in Speculative Decoding(基于时间局部性的层次化草稿实现大语言模型无损加速)
[] 🚀 Show-o Turbo: Towards Accelerated Unified Multimodal Understanding and Generation(Show-o Turbo:迈向加速统一多模态理解和生成)
[] 🤖 Training Language Models for Social Deduction with Multi-Agent Reinforcement Learning(利用多智能体强化学习训练语言模型进行社会推理)
[] 🧠 ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates(ReasonFlux:通过扩展思维模板实现分层LLM推理)
[] 🌐 EVEv2: Improved Baselines for Encoder-Free Vision-Language Models(EVEv2:改进的无编码器视觉语言模型基线)
[] 🧠 LM2: Large Memory Models(大型记忆模型)
[] 🧠 The Hidden Life of Tokens: Reducing Hallucination of Large Vision-Language Models via Visual Information Steering(标记的隐秘生命:通过视觉信息引导减少大型视觉语言模型的幻觉)
[] 🪆 Matryoshka Quantization(嵌套量化)
[] 🎥 Lumina-Video: Efficient and Flexible Video Generation with Multi-scale Next-DiT(Lumina-Video: 多尺度Next-DiT的高效灵活视频生成)
[] 🎥 History-Guided Video Diffusion(历史引导的视频扩散)
[] 🎥 CustomVideoX: 3D Reference Attention Driven Dynamic Adaptation for Zero-Shot Customized Video Diffusion Transformers(CustomVideoX:三维参考注意力驱动的零样本定制视频扩散变换器动态适应)
[] ⚡ APE: Faster and Longer Context-Augmented Generation via Adaptive Parallel Encoding(自适应并行编码:通过自适应并行编码实现更快更长的上下文增强生成)
[] ⏱ Efficient-vDiT: Efficient Video Diffusion Transformers With Attention Tile(高效视频扩散Transformer模型)
[] 🤖 MetaChain: A Fully-Automated and Zero-Code Framework for LLM Agents(元链:一个全自动且无需代码的LLM代理框架)
[] 🚀 Steel-LLM:From Scratch to Open Source -- A Personal Journey in Building a Chinese-Centric LLM(Steel-LLM:从零到开源——构建以中文为中心的LLM的个人历程)
[] 🧠 The Curse of Depth in Large Language Models(深度在大语言模型中的诅咒)
[] 🎨 DreamDPO: Aligning Text-to-3D Generation with Human Preferences via Direct Preference Optimization(DreamDPO:通过直接偏好优化对齐文本到3D生成与人偏好)
[] 🎨 Dual Caption Preference Optimization for Diffusion Models(双标题偏好优化用于扩散模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 2 月 12 日 · 16 分钟
本期的 21 篇论文如下:
[] 🤖 SynthDetoxM: Modern LLMs are Few-Shot Parallel Detoxification Data Annotators(SynthDetoxM:现代大语言模型是少样本并行去毒化数据标注器)
[] 🧠 Exploring the Limit of Outcome Reward for Learning Mathematical Reasoning(探索数学推理中结果奖励的学习极限)
[] 🤔 Can 1B LLM Surpass 405B LLM? Rethinking Compute-Optimal Test-Time Scaling(10亿参数LLM能否超越4050亿参数LLM?重新思考计算最优的测试时缩放)
[] ⚡ Lossless Acceleration of Large Language Models with Hierarchical Drafting based on Temporal Locality in Speculative Decoding(基于时间局部性的层次化草稿实现大语言模型无损加速)
[] 🚀 Show-o Turbo: Towards Accelerated Unified Multimodal Understanding and Generation(Show-o Turbo:迈向加速统一多模态理解和生成)
[] 🤖 Training Language Models for Social Deduction with Multi-Agent Reinforcement Learning(利用多智能体强化学习训练语言模型进行社会推理)
[] 🧠 ReasonFlux: Hierarchical LLM Reasoning via Scaling Thought Templates(ReasonFlux:通过扩展思维模板实现分层LLM推理)
[] 🌐 EVEv2: Improved Baselines for Encoder-Free Vision-Language Models(EVEv2:改进的无编码器视觉语言模型基线)
[] 🧠 LM2: Large Memory Models(大型记忆模型)
[] 🧠 The Hidden Life of Tokens: Reducing Hallucination of Large Vision-Language Models via Visual Information Steering(标记的隐秘生命:通过视觉信息引导减少大型视觉语言模型的幻觉)
[] 🪆 Matryoshka Quantization(嵌套量化)
[] 🎥 Lumina-Video: Efficient and Flexible Video Generation with Multi-scale Next-DiT(Lumina-Video: 多尺度Next-DiT的高效灵活视频生成)
[] 🎥 History-Guided Video Diffusion(历史引导的视频扩散)
[] 🎥 CustomVideoX: 3D Reference Attention Driven Dynamic Adaptation for Zero-Shot Customized Video Diffusion Transformers(CustomVideoX:三维参考注意力驱动的零样本定制视频扩散变换器动态适应)
[] ⚡ APE: Faster and Longer Context-Augmented Generation via Adaptive Parallel Encoding(自适应并行编码:通过自适应并行编码实现更快更长的上下文增强生成)
[] ⏱ Efficient-vDiT: Efficient Video Diffusion Transformers With Attention Tile(高效视频扩散Transformer模型)
[] 🤖 MetaChain: A Fully-Automated and Zero-Code Framework for LLM Agents(元链:一个全自动且无需代码的LLM代理框架)
[] 🚀 Steel-LLM:From Scratch to Open Source -- A Personal Journey in Building a Chinese-Centric LLM(Steel-LLM:从零到开源——构建以中文为中心的LLM的个人历程)
[] 🧠 The Curse of Depth in Large Language Models(深度在大语言模型中的诅咒)
[] 🎨 DreamDPO: Aligning Text-to-3D Generation with Human Preferences via Direct Preference Optimization(DreamDPO:通过直接偏好优化对齐文本到3D生成与人偏好)
[] 🎨 Dual Caption Preference Optimization for Diffusion Models(双标题偏好优化用于扩散模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟