H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
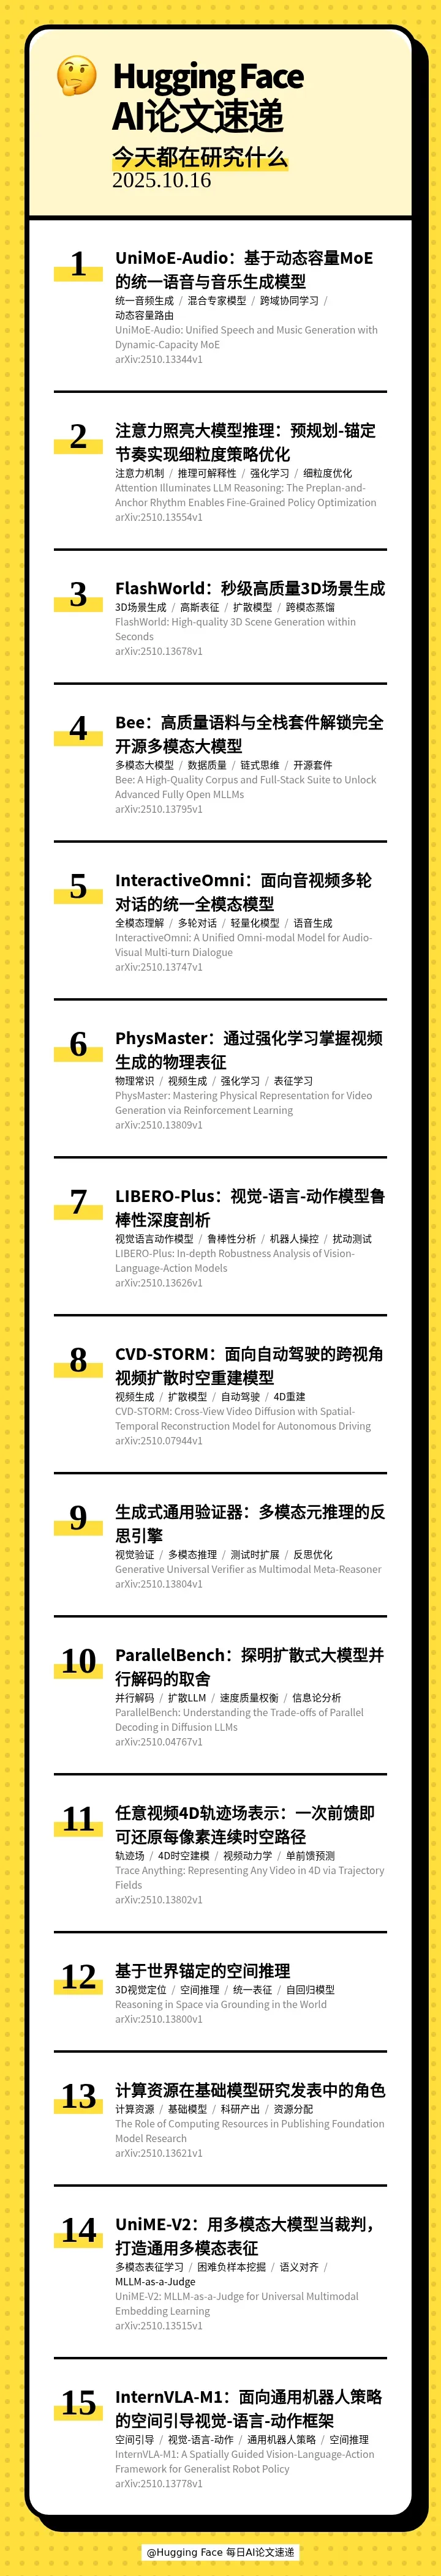
[] 🎧 UniMoE-Audio: Unified Speech and Music Generation with Dynamic-Capacity MoE(UniMoE-Audio:基于动态容量MoE的统一语音与音乐生成模型)
[] 🔍 Attention Illuminates LLM Reasoning: The Preplan-and-Anchor Rhythm Enables Fine-Grained Policy Optimization(注意力照亮大模型推理:预规划-锚定节奏实现细粒度策略优化)
[] ⚡ FlashWorld: High-quality 3D Scene Generation within Seconds(FlashWorld:秒级高质量3D场景生成)
[] 🐝 Bee: A High-Quality Corpus and Full-Stack Suite to Unlock Advanced Fully Open MLLMs(Bee:高质量语料与全栈套件解锁完全开源多模态大模型)
[] 🗣 InteractiveOmni: A Unified Omni-modal Model for Audio-Visual Multi-turn Dialogue(InteractiveOmni:面向音视频多轮对话的统一全模态模型)
[] 🌍 PhysMaster: Mastering Physical Representation for Video Generation via Reinforcement Learning(PhysMaster:通过强化学习掌握视频生成的物理表征)
[] 🧪 LIBERO-Plus: In-depth Robustness Analysis of Vision-Language-Action Models(LIBERO-Plus:视觉-语言-动作模型鲁棒性深度剖析)
[] 🚗 CVD-STORM: Cross-View Video Diffusion with Spatial-Temporal Reconstruction Model for Autonomous Driving(CVD-STORM:面向自动驾驶的跨视角视频扩散时空重建模型)
[] 🔍 Generative Universal Verifier as Multimodal Meta-Reasoner(生成式通用验证器:多模态元推理的反思引擎)
[] ⚖ ParallelBench: Understanding the Trade-offs of Parallel Decoding in Diffusion LLMs(ParallelBench:探明扩散式大模型并行解码的取舍)
[] 🎞 Trace Anything: Representing Any Video in 4D via Trajectory Fields(任意视频4D轨迹场表示:一次前馈即可还原每像素连续时空路径)
[] 🌍 Reasoning in Space via Grounding in the World(基于世界锚定的空间推理)
[] 🧠 The Role of Computing Resources in Publishing Foundation Model Research(计算资源在基础模型研究发表中的角色)
[] ⚖ UniME-V2: MLLM-as-a-Judge for Universal Multimodal Embedding Learning(UniME-V2:用多模态大模型当裁判,打造通用多模态表征)
[] 🤖 InternVLA-M1: A Spatially Guided Vision-Language-Action Framework for Generalist Robot Policy(InternVLA-M1:面向通用机器人策略的空间引导视觉-语言-动作框架)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 10 月 17 日 · 10 分钟
本期的 15 篇论文如下:
[] 🎧 UniMoE-Audio: Unified Speech and Music Generation with Dynamic-Capacity MoE(UniMoE-Audio:基于动态容量MoE的统一语音与音乐生成模型)
[] 🔍 Attention Illuminates LLM Reasoning: The Preplan-and-Anchor Rhythm Enables Fine-Grained Policy Optimization(注意力照亮大模型推理:预规划-锚定节奏实现细粒度策略优化)
[] ⚡ FlashWorld: High-quality 3D Scene Generation within Seconds(FlashWorld:秒级高质量3D场景生成)
[] 🐝 Bee: A High-Quality Corpus and Full-Stack Suite to Unlock Advanced Fully Open MLLMs(Bee:高质量语料与全栈套件解锁完全开源多模态大模型)
[] 🗣 InteractiveOmni: A Unified Omni-modal Model for Audio-Visual Multi-turn Dialogue(InteractiveOmni:面向音视频多轮对话的统一全模态模型)
[] 🌍 PhysMaster: Mastering Physical Representation for Video Generation via Reinforcement Learning(PhysMaster:通过强化学习掌握视频生成的物理表征)
[] 🧪 LIBERO-Plus: In-depth Robustness Analysis of Vision-Language-Action Models(LIBERO-Plus:视觉-语言-动作模型鲁棒性深度剖析)
[] 🚗 CVD-STORM: Cross-View Video Diffusion with Spatial-Temporal Reconstruction Model for Autonomous Driving(CVD-STORM:面向自动驾驶的跨视角视频扩散时空重建模型)
[] 🔍 Generative Universal Verifier as Multimodal Meta-Reasoner(生成式通用验证器:多模态元推理的反思引擎)
[] ⚖ ParallelBench: Understanding the Trade-offs of Parallel Decoding in Diffusion LLMs(ParallelBench:探明扩散式大模型并行解码的取舍)
[] 🎞 Trace Anything: Representing Any Video in 4D via Trajectory Fields(任意视频4D轨迹场表示:一次前馈即可还原每像素连续时空路径)
[] 🌍 Reasoning in Space via Grounding in the World(基于世界锚定的空间推理)
[] 🧠 The Role of Computing Resources in Publishing Foundation Model Research(计算资源在基础模型研究发表中的角色)
[] ⚖ UniME-V2: MLLM-as-a-Judge for Universal Multimodal Embedding Learning(UniME-V2:用多模态大模型当裁判,打造通用多模态表征)
[] 🤖 InternVLA-M1: A Spatially Guided Vision-Language-Action Framework for Generalist Robot Policy(InternVLA-M1:面向通用机器人策略的空间引导视觉-语言-动作框架)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟