H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 14 篇论文如下:
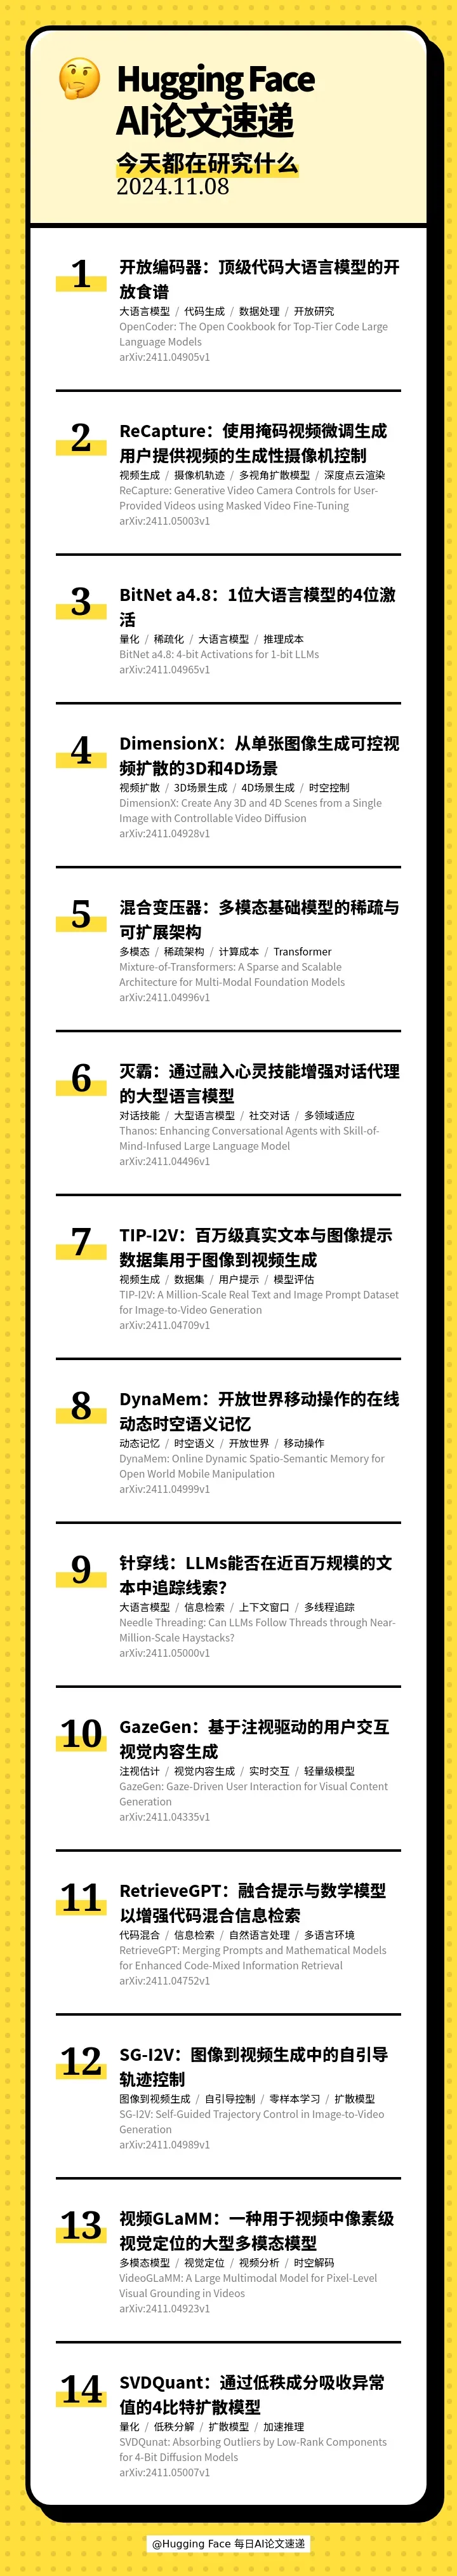
[] 🔧 OpenCoder: The Open Cookbook for Top-Tier Code Large Language Models(开放编码器:顶级代码大语言模型的开放食谱)
[] 🎥 ReCapture: Generative Video Camera Controls for User-Provided Videos using Masked Video Fine-Tuning(ReCapture:使用掩码视频微调生成用户提供视频的生成性摄像机控制)
[] ⚡ BitNet a4.8: 4-bit Activations for 1-bit LLMs(BitNet a4.8:1位大语言模型的4位激活)
[] 🎥 DimensionX: Create Any 3D and 4D Scenes from a Single Image with Controllable Video Diffusion(DimensionX:从单张图像生成可控视频扩散的3D和4D场景)
[] 🤖 Mixture-of-Transformers: A Sparse and Scalable Architecture for Multi-Modal Foundation Models(混合变压器:多模态基础模型的稀疏与可扩展架构)
[] 🧠 Thanos: Enhancing Conversational Agents with Skill-of-Mind-Infused Large Language Model(灭霸:通过融入心灵技能增强对话代理的大型语言模型)
[] 🎥 TIP-I2V: A Million-Scale Real Text and Image Prompt Dataset for Image-to-Video Generation(TIP-I2V:百万级真实文本与图像提示数据集用于图像到视频生成)
[] 🤖 DynaMem: Online Dynamic Spatio-Semantic Memory for Open World Mobile Manipulation(DynaMem:开放世界移动操作的在线动态时空语义记忆)
[] 🧵 Needle Threading: Can LLMs Follow Threads through Near-Million-Scale Haystacks?(针穿线:LLMs能否在近百万规模的文本中追踪线索?)
[] 👀 GazeGen: Gaze-Driven User Interaction for Visual Content Generation(GazeGen:基于注视驱动的用户交互视觉内容生成)
[] 🌐 RetrieveGPT: Merging Prompts and Mathematical Models for Enhanced Code-Mixed Information Retrieval(RetrieveGPT:融合提示与数学模型以增强代码混合信息检索)
[] 🎥 SG-I2V: Self-Guided Trajectory Control in Image-to-Video Generation(SG-I2V:图像到视频生成中的自引导轨迹控制)
[] 🎥 VideoGLaMM: A Large Multimodal Model for Pixel-Level Visual Grounding in Videos(视频GLaMM:一种用于视频中像素级视觉定位的大型多模态模型)
[] ⚡ SVDQunat: Absorbing Outliers by Low-Rank Components for 4-Bit Diffusion Models(SVDQuant:通过低秩成分吸收异常值的4比特扩散模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 11 月 9 日 · 10 分钟
本期的 14 篇论文如下:
[] 🔧 OpenCoder: The Open Cookbook for Top-Tier Code Large Language Models(开放编码器:顶级代码大语言模型的开放食谱)
[] 🎥 ReCapture: Generative Video Camera Controls for User-Provided Videos using Masked Video Fine-Tuning(ReCapture:使用掩码视频微调生成用户提供视频的生成性摄像机控制)
[] ⚡ BitNet a4.8: 4-bit Activations for 1-bit LLMs(BitNet a4.8:1位大语言模型的4位激活)
[] 🎥 DimensionX: Create Any 3D and 4D Scenes from a Single Image with Controllable Video Diffusion(DimensionX:从单张图像生成可控视频扩散的3D和4D场景)
[] 🤖 Mixture-of-Transformers: A Sparse and Scalable Architecture for Multi-Modal Foundation Models(混合变压器:多模态基础模型的稀疏与可扩展架构)
[] 🧠 Thanos: Enhancing Conversational Agents with Skill-of-Mind-Infused Large Language Model(灭霸:通过融入心灵技能增强对话代理的大型语言模型)
[] 🎥 TIP-I2V: A Million-Scale Real Text and Image Prompt Dataset for Image-to-Video Generation(TIP-I2V:百万级真实文本与图像提示数据集用于图像到视频生成)
[] 🤖 DynaMem: Online Dynamic Spatio-Semantic Memory for Open World Mobile Manipulation(DynaMem:开放世界移动操作的在线动态时空语义记忆)
[] 🧵 Needle Threading: Can LLMs Follow Threads through Near-Million-Scale Haystacks?(针穿线:LLMs能否在近百万规模的文本中追踪线索?)
[] 👀 GazeGen: Gaze-Driven User Interaction for Visual Content Generation(GazeGen:基于注视驱动的用户交互视觉内容生成)
[] 🌐 RetrieveGPT: Merging Prompts and Mathematical Models for Enhanced Code-Mixed Information Retrieval(RetrieveGPT:融合提示与数学模型以增强代码混合信息检索)
[] 🎥 SG-I2V: Self-Guided Trajectory Control in Image-to-Video Generation(SG-I2V:图像到视频生成中的自引导轨迹控制)
[] 🎥 VideoGLaMM: A Large Multimodal Model for Pixel-Level Visual Grounding in Videos(视频GLaMM:一种用于视频中像素级视觉定位的大型多模态模型)
[] ⚡ SVDQunat: Absorbing Outliers by Low-Rank Components for 4-Bit Diffusion Models(SVDQuant:通过低秩成分吸收异常值的4比特扩散模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟