H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
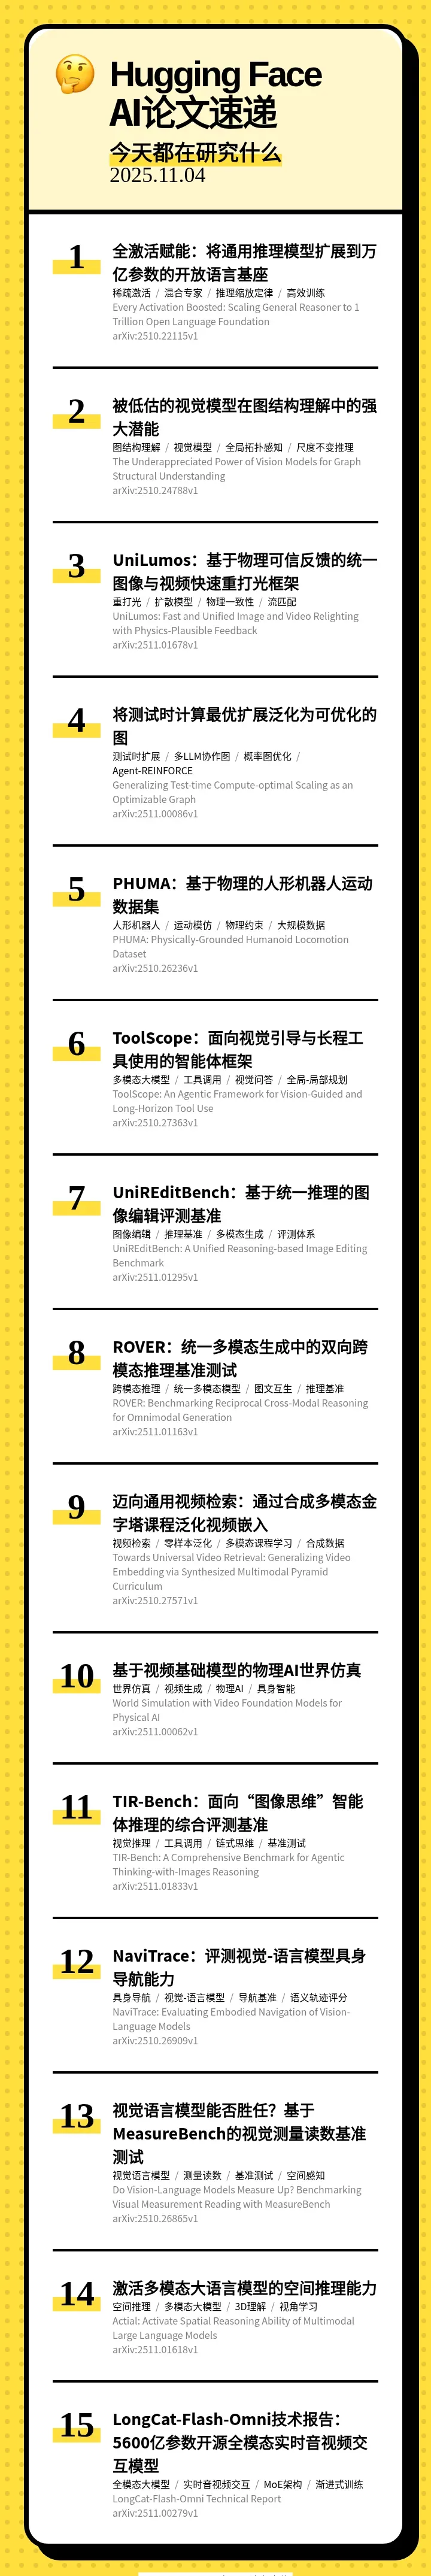
[] 🧠 Every Activation Boosted: Scaling General Reasoner to 1 Trillion Open Language Foundation(全激活赋能:将通用推理模型扩展到万亿参数的开放语言基座)
[] 👁 The Underappreciated Power of Vision Models for Graph Structural Understanding(被低估的视觉模型在图结构理解中的强大潜能)
[] 💡 UniLumos: Fast and Unified Image and Video Relighting with Physics-Plausible Feedback(UniLumos:基于物理可信反馈的统一图像与视频快速重打光框架)
[] 🕸 Generalizing Test-time Compute-optimal Scaling as an Optimizable Graph(将测试时计算最优扩展泛化为可优化的图)
[] 🤖 PHUMA: Physically-Grounded Humanoid Locomotion Dataset(PHUMA:基于物理的人形机器人运动数据集)
[] 🔭 ToolScope: An Agentic Framework for Vision-Guided and Long-Horizon Tool Use(ToolScope:面向视觉引导与长程工具使用的智能体框架)
[] 🧠 UniREditBench: A Unified Reasoning-based Image Editing Benchmark(UniREditBench:基于统一推理的图像编辑评测基准)
[] 🔄 ROVER: Benchmarking Reciprocal Cross-Modal Reasoning for Omnimodal Generation(ROVER:统一多模态生成中的双向跨模态推理基准测试)
[] 🌍 Towards Universal Video Retrieval: Generalizing Video Embedding via Synthesized Multimodal Pyramid Curriculum(迈向通用视频检索:通过合成多模态金字塔课程泛化视频嵌入)
[] 🌍 World Simulation with Video Foundation Models for Physical AI(基于视频基础模型的物理AI世界仿真)
[] 🧠 TIR-Bench: A Comprehensive Benchmark for Agentic Thinking-with-Images Reasoning(TIR-Bench:面向“图像思维”智能体推理的综合评测基准)
[] 🧭 NaviTrace: Evaluating Embodied Navigation of Vision-Language Models(NaviTrace:评测视觉-语言模型具身导航能力)
[] 📏 Do Vision-Language Models Measure Up? Benchmarking Visual Measurement Reading with MeasureBench(视觉语言模型能否胜任?基于MeasureBench的视觉测量读数基准测试)
[] 🧭 Actial: Activate Spatial Reasoning Ability of Multimodal Large Language Models(激活多模态大语言模型的空间推理能力)
[] 🐱 LongCat-Flash-Omni Technical Report(LongCat-Flash-Omni技术报告:5600亿参数开源全模态实时音视频交互模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 11 月 5 日 · 11 分钟
本期的 15 篇论文如下:
[] 🧠 Every Activation Boosted: Scaling General Reasoner to 1 Trillion Open Language Foundation(全激活赋能:将通用推理模型扩展到万亿参数的开放语言基座)
[] 👁 The Underappreciated Power of Vision Models for Graph Structural Understanding(被低估的视觉模型在图结构理解中的强大潜能)
[] 💡 UniLumos: Fast and Unified Image and Video Relighting with Physics-Plausible Feedback(UniLumos:基于物理可信反馈的统一图像与视频快速重打光框架)
[] 🕸 Generalizing Test-time Compute-optimal Scaling as an Optimizable Graph(将测试时计算最优扩展泛化为可优化的图)
[] 🤖 PHUMA: Physically-Grounded Humanoid Locomotion Dataset(PHUMA:基于物理的人形机器人运动数据集)
[] 🔭 ToolScope: An Agentic Framework for Vision-Guided and Long-Horizon Tool Use(ToolScope:面向视觉引导与长程工具使用的智能体框架)
[] 🧠 UniREditBench: A Unified Reasoning-based Image Editing Benchmark(UniREditBench:基于统一推理的图像编辑评测基准)
[] 🔄 ROVER: Benchmarking Reciprocal Cross-Modal Reasoning for Omnimodal Generation(ROVER:统一多模态生成中的双向跨模态推理基准测试)
[] 🌍 Towards Universal Video Retrieval: Generalizing Video Embedding via Synthesized Multimodal Pyramid Curriculum(迈向通用视频检索:通过合成多模态金字塔课程泛化视频嵌入)
[] 🌍 World Simulation with Video Foundation Models for Physical AI(基于视频基础模型的物理AI世界仿真)
[] 🧠 TIR-Bench: A Comprehensive Benchmark for Agentic Thinking-with-Images Reasoning(TIR-Bench:面向“图像思维”智能体推理的综合评测基准)
[] 🧭 NaviTrace: Evaluating Embodied Navigation of Vision-Language Models(NaviTrace:评测视觉-语言模型具身导航能力)
[] 📏 Do Vision-Language Models Measure Up? Benchmarking Visual Measurement Reading with MeasureBench(视觉语言模型能否胜任?基于MeasureBench的视觉测量读数基准测试)
[] 🧭 Actial: Activate Spatial Reasoning Ability of Multimodal Large Language Models(激活多模态大语言模型的空间推理能力)
[] 🐱 LongCat-Flash-Omni Technical Report(LongCat-Flash-Omni技术报告:5600亿参数开源全模态实时音视频交互模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟