H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
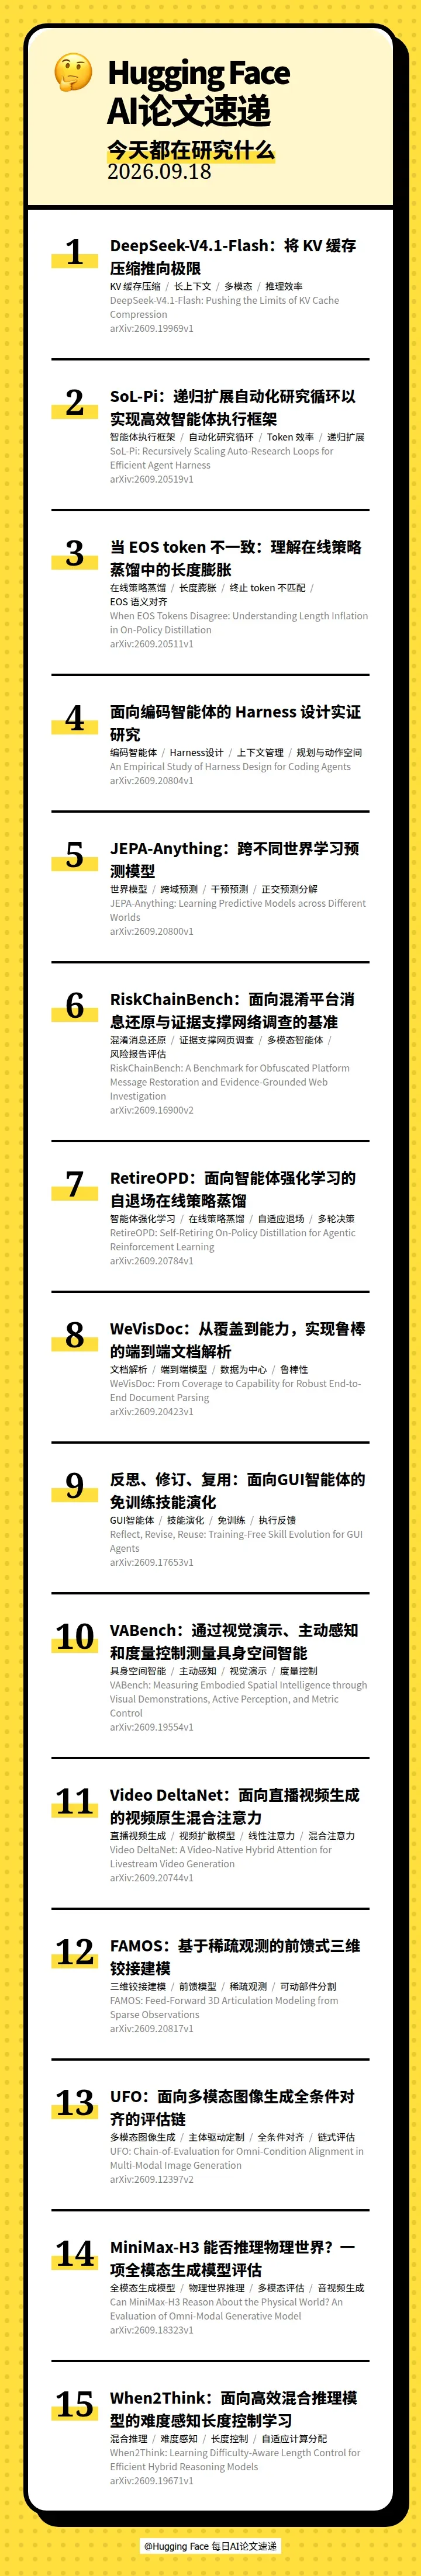
[] 🗜 DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression(DeepSeek-V4.1-Flash:将 KV 缓存压缩推向极限)
[] ⚡ SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness(SoL-Pi:递归扩展自动化研究循环以实现高效智能体执行框架)
[] 🛑 When EOS Tokens Disagree: Understanding Length Inflation in On-Policy Distillation(当 EOS token 不一致:理解在线策略蒸馏中的长度膨胀)
[] 🧪 An Empirical Study of Harness Design for Coding Agents(面向编码智能体的 Harness 设计实证研究)
[] 🌍 JEPA-Anything: Learning Predictive Models across Different Worlds(JEPA-Anything:跨不同世界学习预测模型)
[] 🕵 RiskChainBench: A Benchmark for Obfuscated Platform Message Restoration and Evidence-Grounded Web Investigation(RiskChainBench:面向混淆平台消息还原与证据支撑网络调查的基准)
[] 🎓 RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning(RetireOPD:面向智能体强化学习的自退场在线策略蒸馏)
[] 📄 WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing(WeVisDoc:从覆盖到能力,实现鲁棒的端到端文档解析)
[] 🔄 Reflect, Revise, Reuse: Training-Free Skill Evolution for GUI Agents(反思、修订、复用:面向GUI智能体的免训练技能演化)
[] 🤖 VABench: Measuring Embodied Spatial Intelligence through Visual Demonstrations, Active Perception, and Metric Control(VABench:通过视觉演示、主动感知和度量控制测量具身空间智能)
[] 🎥 Video DeltaNet: A Video-Native Hybrid Attention for Livestream Video Generation(Video DeltaNet:面向直播视频生成的视频原生混合注意力)
[] 🦾 FAMOS: Feed-Forward 3D Articulation Modeling from Sparse Observations(FAMOS:基于稀疏观测的前馈式三维铰接建模)
[] 🖼 UFO: Chain-of-Evaluation for Omni-Condition Alignment in Multi-Modal Image Generation(UFO:面向多模态图像生成全条件对齐的评估链)
[] 🌍 Can MiniMax-H3 Reason About the Physical World? An Evaluation of Omni-Modal Generative Model(MiniMax-H3 能否推理物理世界?一项全模态生成模型评估)
[] 🧠 When2Think: Learning Difficulty-Aware Length Control for Efficient Hybrid Reasoning Models(When2Think:面向高效混合推理模型的难度感知长度控制学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 9 月 19 日 · 12 分钟
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
[] 🗜 DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression(DeepSeek-V4.1-Flash:将 KV 缓存压缩推向极限)
[] ⚡ SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness(SoL-Pi:递归扩展自动化研究循环以实现高效智能体执行框架)
[] 🛑 When EOS Tokens Disagree: Understanding Length Inflation in On-Policy Distillation(当 EOS token 不一致:理解在线策略蒸馏中的长度膨胀)
[] 🧪 An Empirical Study of Harness Design for Coding Agents(面向编码智能体的 Harness 设计实证研究)
[] 🌍 JEPA-Anything: Learning Predictive Models across Different Worlds(JEPA-Anything:跨不同世界学习预测模型)
[] 🕵 RiskChainBench: A Benchmark for Obfuscated Platform Message Restoration and Evidence-Grounded Web Investigation(RiskChainBench:面向混淆平台消息还原与证据支撑网络调查的基准)
[] 🎓 RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning(RetireOPD:面向智能体强化学习的自退场在线策略蒸馏)
[] 📄 WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing(WeVisDoc:从覆盖到能力,实现鲁棒的端到端文档解析)
[] 🔄 Reflect, Revise, Reuse: Training-Free Skill Evolution for GUI Agents(反思、修订、复用:面向GUI智能体的免训练技能演化)
[] 🤖 VABench: Measuring Embodied Spatial Intelligence through Visual Demonstrations, Active Perception, and Metric Control(VABench:通过视觉演示、主动感知和度量控制测量具身空间智能)
[] 🎥 Video DeltaNet: A Video-Native Hybrid Attention for Livestream Video Generation(Video DeltaNet:面向直播视频生成的视频原生混合注意力)
[] 🦾 FAMOS: Feed-Forward 3D Articulation Modeling from Sparse Observations(FAMOS:基于稀疏观测的前馈式三维铰接建模)
[] 🖼 UFO: Chain-of-Evaluation for Omni-Condition Alignment in Multi-Modal Image Generation(UFO:面向多模态图像生成全条件对齐的评估链)
[] 🌍 Can MiniMax-H3 Reason About the Physical World? An Evaluation of Omni-Modal Generative Model(MiniMax-H3 能否推理物理世界?一项全模态生成模型评估)
[] 🧠 When2Think: Learning Difficulty-Aware Length Control for Efficient Hybrid Reasoning Models(When2Think:面向高效混合推理模型的难度感知长度控制学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟