H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 23 篇论文如下:
[] 🔍 VisionZip: Longer is Better but Not Necessary in Vision Language Models(视觉压缩:视觉语言模型中长度并非必要优势)
[] 🤖 Code-as-Monitor: Constraint-aware Visual Programming for Reactive and Proactive Robotic Failure Detection(代码即监控:约束感知的视觉编程用于反应性和前瞻性机器人故障检测)
[] 🖥 Aguvis: Unified Pure Vision Agents for Autonomous GUI Interaction(Aguvis:统一纯视觉自主GUI交互代理)
[] 🔊 A Noise is Worth Diffusion Guidance(噪声值得扩散引导)
[] 📊 Evaluating Language Models as Synthetic Data Generators(评估语言模型作为合成数据生成器)
[] 🌐 Structured 3D Latents for Scalable and Versatile 3D Generation(结构化3D潜在表示在可扩展和多功能3D生成中的应用)
[] 🌐 MV-Adapter: Multi-view Consistent Image Generation Made Easy(MV-Adapter:多视角一致图像生成变得简单)
[] 🖼 Negative Token Merging: Image-based Adversarial Feature Guidance(负向标记合并:基于图像的对抗特征引导)
[] 🌐 Florence-VL: Enhancing Vision-Language Models with Generative Vision Encoder and Depth-Breadth Fusion(佛罗伦萨-VL:通过生成视觉编码器和深度-广度融合增强视觉语言模型)
[] 📈 Densing Law of LLMs(大语言模型的密度定律)
[] 🌌 Infinity: Scaling Bitwise AutoRegressive Modeling for High-Resolution Image Synthesis(无限:高分辨率图像合成中的比特位自回归建模)
[] ⚽ Towards Universal Soccer Video Understanding(面向通用足球视频理解)
[] 🎨 HumanEdit: A High-Quality Human-Rewarded Dataset for Instruction-based Image Editing(HumanEdit:一个高质量的人类奖励数据集,用于基于指令的图像编辑)
[] 👗 AnyDressing: Customizable Multi-Garment Virtual Dressing via Latent Diffusion Models(任意服装虚拟试穿:基于潜在扩散模型的可定制多服装生成)
[] 🌍 Global MMLU: Understanding and Addressing Cultural and Linguistic Biases in Multilingual Evaluation(全球MMLU:理解和解决多语言评估中的文化和语言偏见)
[] 🌐 Personalized Multimodal Large Language Models: A Survey(个性化多模态大语言模型:综述)
[] ⚡ ZipAR: Accelerating Autoregressive Image Generation through Spatial Locality(ZipAR:通过空间局部性加速自回归图像生成)
[] 🧠 MRGen: Diffusion-based Controllable Data Engine for MRI Segmentation towards Unannotated Modalities(MRGen:基于扩散的可控数据引擎用于无标注模态的MRI分割)
[] 🧠 Discriminative Fine-tuning of LVLMs(判别性微调的大视觉语言模型)
[] 🧠 Monet: Mixture of Monosemantic Experts for Transformers(Monet:Transformer的单语义专家混合模型)
[] 🌊 OmniFlow: Any-to-Any Generation with Multi-Modal Rectified Flows(全流:多模态校正流的任意到任意生成)
[] 🧠 KV Shifting Attention Enhances Language Modeling(KV移位注意力增强语言建模)
[] 🌍 Marco-LLM: Bridging Languages via Massive Multilingual Training for Cross-Lingual Enhancement(Marco-LLM:通过大规模多语言训练实现跨语言增强)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 12 月 7 日 · 16 分钟
本期的 23 篇论文如下:
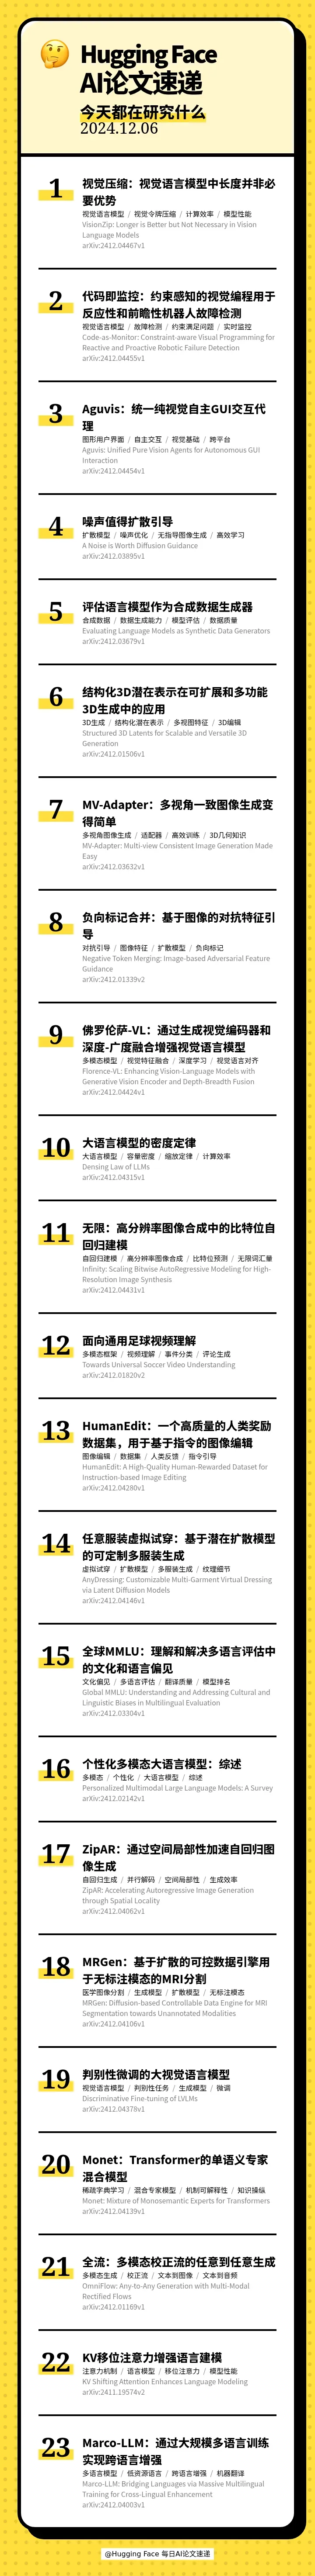
[] 🔍 VisionZip: Longer is Better but Not Necessary in Vision Language Models(视觉压缩:视觉语言模型中长度并非必要优势)
[] 🤖 Code-as-Monitor: Constraint-aware Visual Programming for Reactive and Proactive Robotic Failure Detection(代码即监控:约束感知的视觉编程用于反应性和前瞻性机器人故障检测)
[] 🖥 Aguvis: Unified Pure Vision Agents for Autonomous GUI Interaction(Aguvis:统一纯视觉自主GUI交互代理)
[] 🔊 A Noise is Worth Diffusion Guidance(噪声值得扩散引导)
[] 📊 Evaluating Language Models as Synthetic Data Generators(评估语言模型作为合成数据生成器)
[] 🌐 Structured 3D Latents for Scalable and Versatile 3D Generation(结构化3D潜在表示在可扩展和多功能3D生成中的应用)
[] 🌐 MV-Adapter: Multi-view Consistent Image Generation Made Easy(MV-Adapter:多视角一致图像生成变得简单)
[] 🖼 Negative Token Merging: Image-based Adversarial Feature Guidance(负向标记合并:基于图像的对抗特征引导)
[] 🌐 Florence-VL: Enhancing Vision-Language Models with Generative Vision Encoder and Depth-Breadth Fusion(佛罗伦萨-VL:通过生成视觉编码器和深度-广度融合增强视觉语言模型)
[] 📈 Densing Law of LLMs(大语言模型的密度定律)
[] 🌌 Infinity: Scaling Bitwise AutoRegressive Modeling for High-Resolution Image Synthesis(无限:高分辨率图像合成中的比特位自回归建模)
[] ⚽ Towards Universal Soccer Video Understanding(面向通用足球视频理解)
[] 🎨 HumanEdit: A High-Quality Human-Rewarded Dataset for Instruction-based Image Editing(HumanEdit:一个高质量的人类奖励数据集,用于基于指令的图像编辑)
[] 👗 AnyDressing: Customizable Multi-Garment Virtual Dressing via Latent Diffusion Models(任意服装虚拟试穿:基于潜在扩散模型的可定制多服装生成)
[] 🌍 Global MMLU: Understanding and Addressing Cultural and Linguistic Biases in Multilingual Evaluation(全球MMLU:理解和解决多语言评估中的文化和语言偏见)
[] 🌐 Personalized Multimodal Large Language Models: A Survey(个性化多模态大语言模型:综述)
[] ⚡ ZipAR: Accelerating Autoregressive Image Generation through Spatial Locality(ZipAR:通过空间局部性加速自回归图像生成)
[] 🧠 MRGen: Diffusion-based Controllable Data Engine for MRI Segmentation towards Unannotated Modalities(MRGen:基于扩散的可控数据引擎用于无标注模态的MRI分割)
[] 🧠 Discriminative Fine-tuning of LVLMs(判别性微调的大视觉语言模型)
[] 🧠 Monet: Mixture of Monosemantic Experts for Transformers(Monet:Transformer的单语义专家混合模型)
[] 🌊 OmniFlow: Any-to-Any Generation with Multi-Modal Rectified Flows(全流:多模态校正流的任意到任意生成)
[] 🧠 KV Shifting Attention Enhances Language Modeling(KV移位注意力增强语言建模)
[] 🌍 Marco-LLM: Bridging Languages via Massive Multilingual Training for Cross-Lingual Enhancement(Marco-LLM:通过大规模多语言训练实现跨语言增强)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟