H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
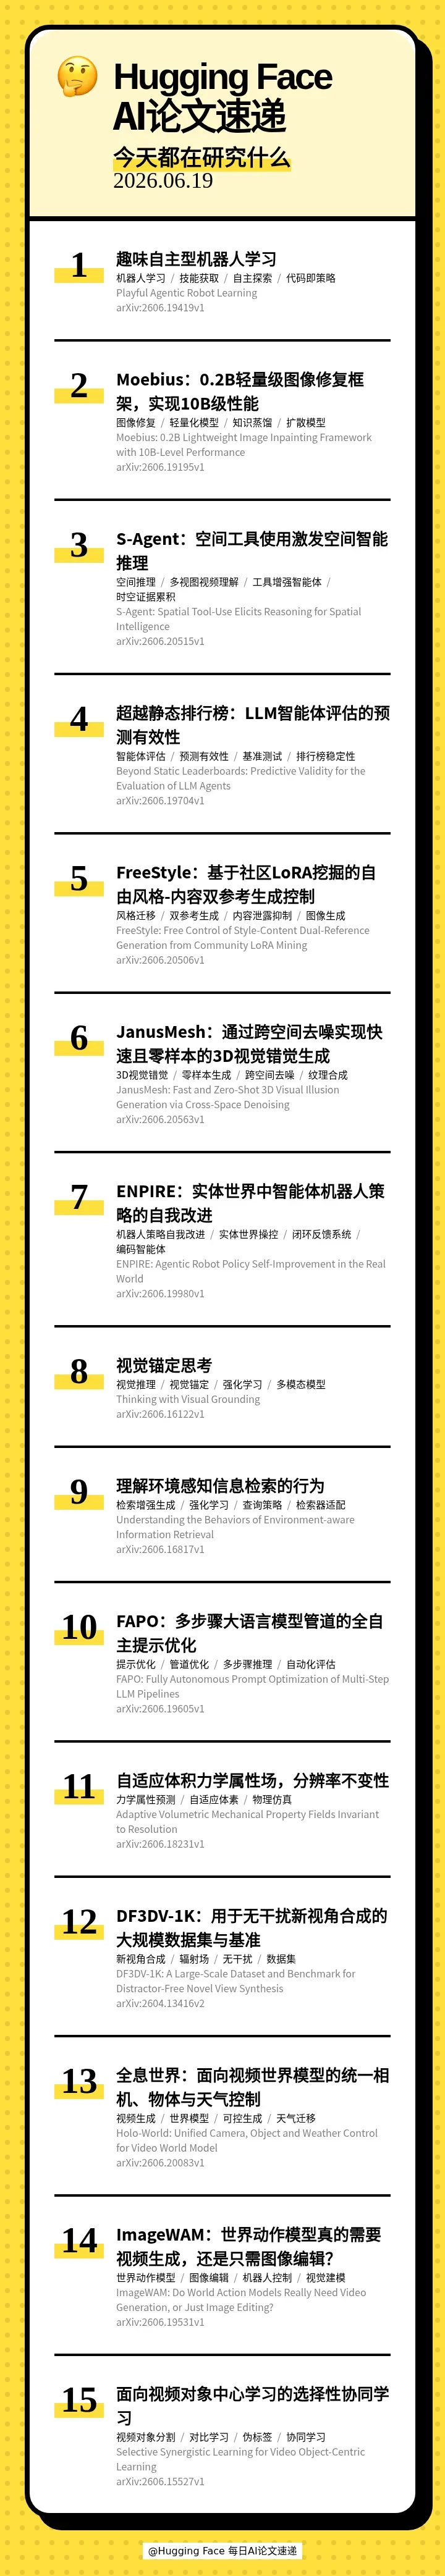
本期的 15 篇论文如下:
[] 🤖 Playful Agentic Robot Learning(趣味自主型机器人学习)
[] 🎨 Moebius: 0.2B Lightweight Image Inpainting Framework with 10B-Level Performance(Moebius:0.2B轻量级图像修复框架,实现10B级性能)
[] 🧠 S-Agent: Spatial Tool-Use Elicits Reasoning for Spatial Intelligence(S-Agent:空间工具使用激发空间智能推理)
[] 📊 Beyond Static Leaderboards: Predictive Validity for the Evaluation of LLM Agents(超越静态排行榜:LLM智能体评估的预测有效性)
[] 🎨 FreeStyle: Free Control of Style-Content Dual-Reference Generation from Community LoRA Mining(FreeStyle:基于社区LoRA挖掘的自由风格-内容双参考生成控制)
[] 🪄 JanusMesh: Fast and Zero-Shot 3D Visual Illusion Generation via Cross-Space Denoising(JanusMesh:通过跨空间去噪实现快速且零样本的3D视觉错觉生成)
[] 🤖 ENPIRE: Agentic Robot Policy Self-Improvement in the Real World(ENPIRE:实体世界中智能体机器人策略的自我改进)
[] 👁 Thinking with Visual Grounding(视觉锚定思考)
[] 🔍 Understanding the Behaviors of Environment-aware Information Retrieval(理解环境感知信息检索的行为)
[] 🤖 FAPO: Fully Autonomous Prompt Optimization of Multi-Step LLM Pipelines(FAPO:多步骤大语言模型管道的全自主提示优化)
[] 🧊 Adaptive Volumetric Mechanical Property Fields Invariant to Resolution(自适应体积力学属性场,分辨率不变性)
[] 📸 DF3DV-1K: A Large-Scale Dataset and Benchmark for Distractor-Free Novel View Synthesis(DF3DV-1K:用于无干扰新视角合成的大规模数据集与基准)
[] 🌍 Holo-World: Unified Camera, Object and Weather Control for Video World Model(全息世界:面向视频世界模型的统一相机、物体与天气控制)
[] 🎨 ImageWAM: Do World Action Models Really Need Video Generation, or Just Image Editing?(ImageWAM:世界动作模型真的需要视频生成,还是只需图像编辑?)
[] 🎯 Selective Synergistic Learning for Video Object-Centric Learning(面向视频对象中心学习的选择性协同学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 6 月 20 日 · 15 分钟
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
[] 🤖 Playful Agentic Robot Learning(趣味自主型机器人学习)
[] 🎨 Moebius: 0.2B Lightweight Image Inpainting Framework with 10B-Level Performance(Moebius:0.2B轻量级图像修复框架,实现10B级性能)
[] 🧠 S-Agent: Spatial Tool-Use Elicits Reasoning for Spatial Intelligence(S-Agent:空间工具使用激发空间智能推理)
[] 📊 Beyond Static Leaderboards: Predictive Validity for the Evaluation of LLM Agents(超越静态排行榜:LLM智能体评估的预测有效性)
[] 🎨 FreeStyle: Free Control of Style-Content Dual-Reference Generation from Community LoRA Mining(FreeStyle:基于社区LoRA挖掘的自由风格-内容双参考生成控制)
[] 🪄 JanusMesh: Fast and Zero-Shot 3D Visual Illusion Generation via Cross-Space Denoising(JanusMesh:通过跨空间去噪实现快速且零样本的3D视觉错觉生成)
[] 🤖 ENPIRE: Agentic Robot Policy Self-Improvement in the Real World(ENPIRE:实体世界中智能体机器人策略的自我改进)
[] 👁 Thinking with Visual Grounding(视觉锚定思考)
[] 🔍 Understanding the Behaviors of Environment-aware Information Retrieval(理解环境感知信息检索的行为)
[] 🤖 FAPO: Fully Autonomous Prompt Optimization of Multi-Step LLM Pipelines(FAPO:多步骤大语言模型管道的全自主提示优化)
[] 🧊 Adaptive Volumetric Mechanical Property Fields Invariant to Resolution(自适应体积力学属性场,分辨率不变性)
[] 📸 DF3DV-1K: A Large-Scale Dataset and Benchmark for Distractor-Free Novel View Synthesis(DF3DV-1K:用于无干扰新视角合成的大规模数据集与基准)
[] 🌍 Holo-World: Unified Camera, Object and Weather Control for Video World Model(全息世界:面向视频世界模型的统一相机、物体与天气控制)
[] 🎨 ImageWAM: Do World Action Models Really Need Video Generation, or Just Image Editing?(ImageWAM:世界动作模型真的需要视频生成,还是只需图像编辑?)
[] 🎯 Selective Synergistic Learning for Video Object-Centric Learning(面向视频对象中心学习的选择性协同学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟