H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

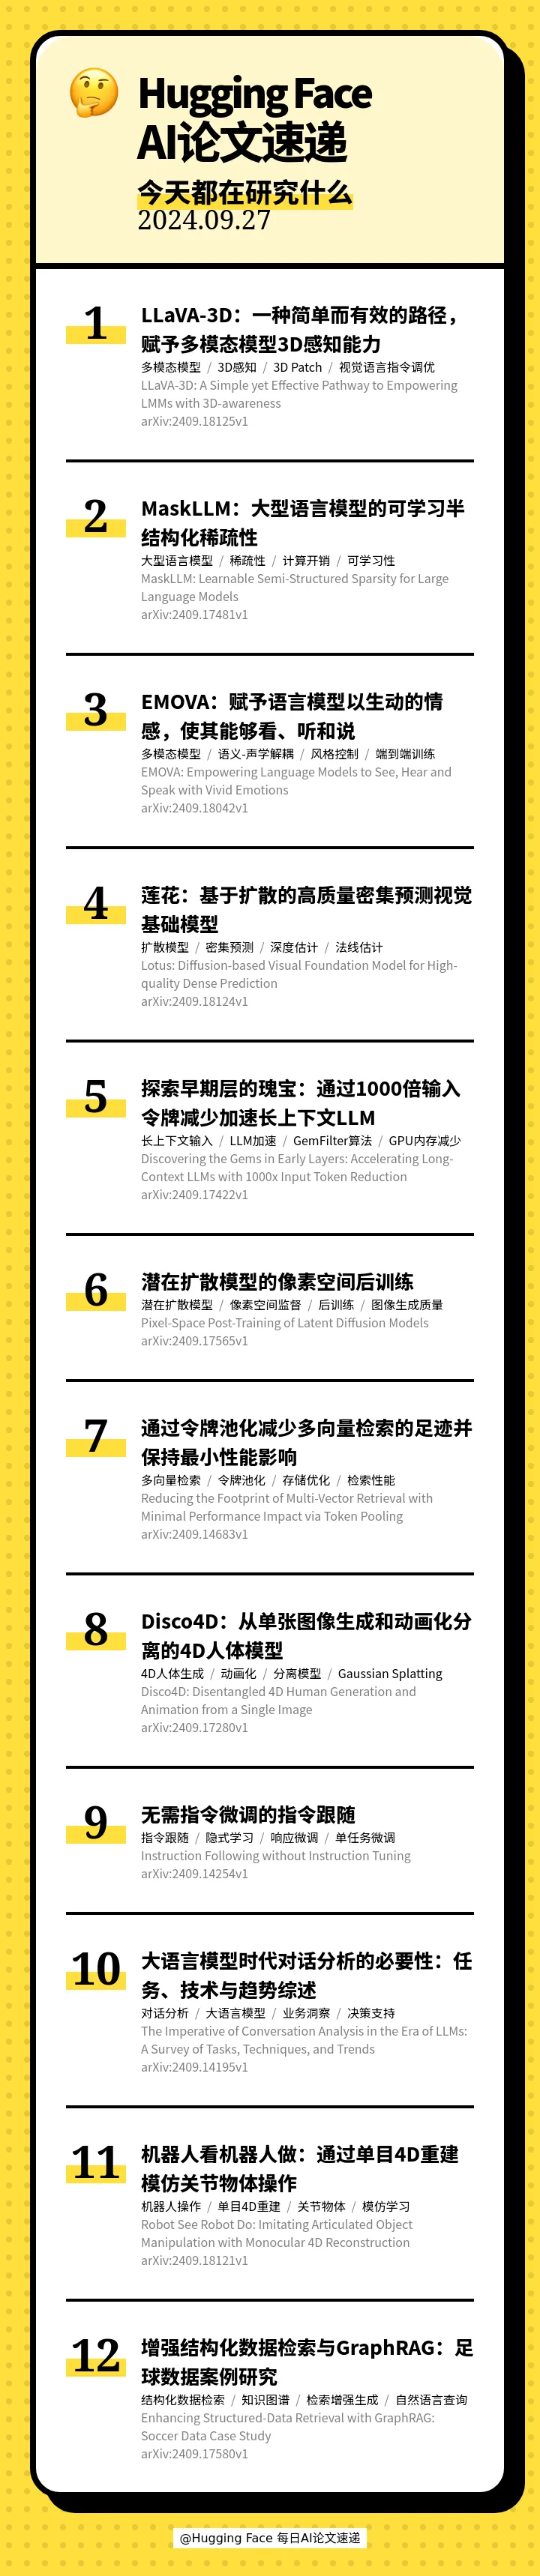
本期的 12 篇论文如下:
[] 🌐 LLaVA-3D: A Simple yet Effective Pathway to Empowering LMMs with 3D-awareness(LLaVA-3D:一种简单而有效的路径,赋予多模态模型3D感知能力)
[] 🧩 MaskLLM: Learnable Semi-Structured Sparsity for Large Language Models(MaskLLM:大型语言模型的可学习半结构化稀疏性)
[] 🎭 EMOVA: Empowering Language Models to See, Hear and Speak with Vivid Emotions(EMOVA:赋予语言模型以生动的情感,使其能够看、听和说)
[] 🌸 Lotus: Diffusion-based Visual Foundation Model for High-quality Dense Prediction(莲花:基于扩散的高质量密集预测视觉基础模型)
[] ⚡ Discovering the Gems in Early Layers: Accelerating Long-Context LLMs with 1000x Input Token Reduction(探索早期层的瑰宝:通过1000倍输入令牌减少加速长上下文LLM)
[] 🖼 Pixel-Space Post-Training of Latent Diffusion Models(潜在扩散模型的像素空间后训练)
[] 🔍 Reducing the Footprint of Multi-Vector Retrieval with Minimal Performance Impact via Token Pooling(通过令牌池化减少多向量检索的足迹并保持最小性能影响)
[] 🎭 Disco4D: Disentangled 4D Human Generation and Animation from a Single Image(Disco4D:从单张图像生成和动画化分离的4D人体模型)
[] 🧠 Instruction Following without Instruction Tuning(无需指令微调的指令跟随)
[] 📊 The Imperative of Conversation Analysis in the Era of LLMs: A Survey of Tasks, Techniques, and Trends(大语言模型时代对话分析的必要性:任务、技术与趋势综述)
[] 🤖 Robot See Robot Do: Imitating Articulated Object Manipulation with Monocular 4D Reconstruction(机器人看机器人做:通过单目4D重建模仿关节物体操作)
[] ⚽ Enhancing Structured-Data Retrieval with GraphRAG: Soccer Data Case Study(增强结构化数据检索与GraphRAG:足球数据案例研究)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 9 月 28 日 · 9 分钟
本期的 12 篇论文如下:
[] 🌐 LLaVA-3D: A Simple yet Effective Pathway to Empowering LMMs with 3D-awareness(LLaVA-3D:一种简单而有效的路径,赋予多模态模型3D感知能力)
[] 🧩 MaskLLM: Learnable Semi-Structured Sparsity for Large Language Models(MaskLLM:大型语言模型的可学习半结构化稀疏性)
[] 🎭 EMOVA: Empowering Language Models to See, Hear and Speak with Vivid Emotions(EMOVA:赋予语言模型以生动的情感,使其能够看、听和说)
[] 🌸 Lotus: Diffusion-based Visual Foundation Model for High-quality Dense Prediction(莲花:基于扩散的高质量密集预测视觉基础模型)
[] ⚡ Discovering the Gems in Early Layers: Accelerating Long-Context LLMs with 1000x Input Token Reduction(探索早期层的瑰宝:通过1000倍输入令牌减少加速长上下文LLM)
[] 🖼 Pixel-Space Post-Training of Latent Diffusion Models(潜在扩散模型的像素空间后训练)
[] 🔍 Reducing the Footprint of Multi-Vector Retrieval with Minimal Performance Impact via Token Pooling(通过令牌池化减少多向量检索的足迹并保持最小性能影响)
[] 🎭 Disco4D: Disentangled 4D Human Generation and Animation from a Single Image(Disco4D:从单张图像生成和动画化分离的4D人体模型)
[] 🧠 Instruction Following without Instruction Tuning(无需指令微调的指令跟随)
[] 📊 The Imperative of Conversation Analysis in the Era of LLMs: A Survey of Tasks, Techniques, and Trends(大语言模型时代对话分析的必要性:任务、技术与趋势综述)
[] 🤖 Robot See Robot Do: Imitating Articulated Object Manipulation with Monocular 4D Reconstruction(机器人看机器人做:通过单目4D重建模仿关节物体操作)
[] ⚽ Enhancing Structured-Data Retrieval with GraphRAG: Soccer Data Case Study(增强结构化数据检索与GraphRAG:足球数据案例研究)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟