H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【赞助商】
通勤路上就听AI每周谈。AI每周谈,每周带你回顾上周AI大事
传送门 🔗https://www.xiaoyuzhoufm.com/podcast/688a34636f5a275f1cba40fd
【目录】
本期的 15 篇论文如下:
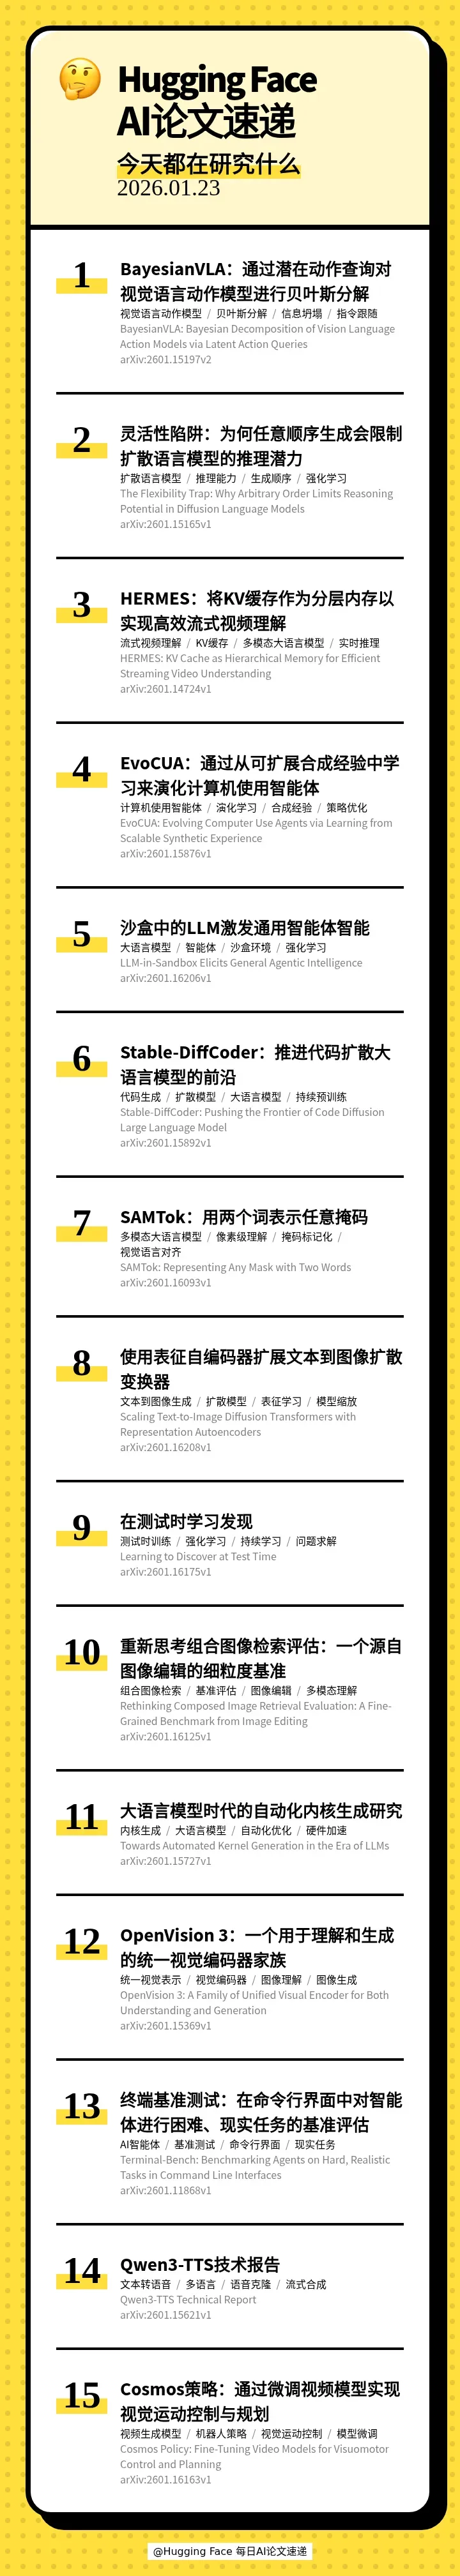
[] 🤖 BayesianVLA: Bayesian Decomposition of Vision Language Action Models via Latent Action Queries(BayesianVLA:通过潜在动作查询对视觉语言动作模型进行贝叶斯分解)
[] ⚠ The Flexibility Trap: Why Arbitrary Order Limits Reasoning Potential in Diffusion Language Models(灵活性陷阱:为何任意顺序生成会限制扩散语言模型的推理潜力)
[] 🎥 HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video Understanding(HERMES:将KV缓存作为分层内存以实现高效流式视频理解)
[] 🚀 EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience(EvoCUA:通过从可扩展合成经验中学习来演化计算机使用智能体)
[] 🧪 LLM-in-Sandbox Elicits General Agentic Intelligence(沙盒中的LLM激发通用智能体智能)
[] 🚀 Stable-DiffCoder: Pushing the Frontier of Code Diffusion Large Language Model(Stable-DiffCoder:推进代码扩散大语言模型的前沿)
[] 🎭 SAMTok: Representing Any Mask with Two Words(SAMTok:用两个词表示任意掩码)
[] 🚀 Scaling Text-to-Image Diffusion Transformers with Representation Autoencoders(使用表征自编码器扩展文本到图像扩散变换器)
[] 🔬 Learning to Discover at Test Time(在测试时学习发现)
[] 🔍 Rethinking Composed Image Retrieval Evaluation: A Fine-Grained Benchmark from Image Editing(重新思考组合图像检索评估:一个源自图像编辑的细粒度基准)
[] ⚙ Towards Automated Kernel Generation in the Era of LLMs(大语言模型时代的自动化内核生成研究)
[] 🔄 OpenVision 3: A Family of Unified Visual Encoder for Both Understanding and Generation(OpenVision 3:一个用于理解和生成的统一视觉编码器家族)
[] 💻 Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces(终端基准测试:在命令行界面中对智能体进行困难、现实任务的基准评估)
[] 🗣 Qwen3-TTS Technical Report(Qwen3-TTS技术报告)
[] 🤖 Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning(Cosmos策略:通过微调视频模型实现视觉运动控制与规划)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 1 月 24 日 · 14 分钟
【赞助商】
通勤路上就听AI每周谈。AI每周谈,每周带你回顾上周AI大事
传送门 🔗https://www.xiaoyuzhoufm.com/podcast/688a34636f5a275f1cba40fd
【目录】
本期的 15 篇论文如下:
[] 🤖 BayesianVLA: Bayesian Decomposition of Vision Language Action Models via Latent Action Queries(BayesianVLA:通过潜在动作查询对视觉语言动作模型进行贝叶斯分解)
[] ⚠ The Flexibility Trap: Why Arbitrary Order Limits Reasoning Potential in Diffusion Language Models(灵活性陷阱:为何任意顺序生成会限制扩散语言模型的推理潜力)
[] 🎥 HERMES: KV Cache as Hierarchical Memory for Efficient Streaming Video Understanding(HERMES:将KV缓存作为分层内存以实现高效流式视频理解)
[] 🚀 EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience(EvoCUA:通过从可扩展合成经验中学习来演化计算机使用智能体)
[] 🧪 LLM-in-Sandbox Elicits General Agentic Intelligence(沙盒中的LLM激发通用智能体智能)
[] 🚀 Stable-DiffCoder: Pushing the Frontier of Code Diffusion Large Language Model(Stable-DiffCoder:推进代码扩散大语言模型的前沿)
[] 🎭 SAMTok: Representing Any Mask with Two Words(SAMTok:用两个词表示任意掩码)
[] 🚀 Scaling Text-to-Image Diffusion Transformers with Representation Autoencoders(使用表征自编码器扩展文本到图像扩散变换器)
[] 🔬 Learning to Discover at Test Time(在测试时学习发现)
[] 🔍 Rethinking Composed Image Retrieval Evaluation: A Fine-Grained Benchmark from Image Editing(重新思考组合图像检索评估:一个源自图像编辑的细粒度基准)
[] ⚙ Towards Automated Kernel Generation in the Era of LLMs(大语言模型时代的自动化内核生成研究)
[] 🔄 OpenVision 3: A Family of Unified Visual Encoder for Both Understanding and Generation(OpenVision 3:一个用于理解和生成的统一视觉编码器家族)
[] 💻 Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces(终端基准测试:在命令行界面中对智能体进行困难、现实任务的基准评估)
[] 🗣 Qwen3-TTS Technical Report(Qwen3-TTS技术报告)
[] 🤖 Cosmos Policy: Fine-Tuning Video Models for Visuomotor Control and Planning(Cosmos策略:通过微调视频模型实现视觉运动控制与规划)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟