H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 12 篇论文如下:
[] 💡 GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning(GLM-4.1V-Thinking:基于可扩展强化学习的通用多模态推理)
[] 🖼 MoCa: Modality-aware Continual Pre-training Makes Better Bidirectional Multimodal Embeddings(MoCa:模态感知持续预训练提升双向多模态嵌入效果)
[] 🔬 SciArena: An Open Evaluation Platform for Foundation Models in Scientific Literature Tasks(SciArena:科学文献任务中基础模型的开放评估平台)
[] 🤔 Does Math Reasoning Improve General LLM Capabilities? Understanding Transferability of LLM Reasoning(数学推理能力是否能提升通用大语言模型的能力?理解大语言模型推理的迁移性)
[] 🎬 Radial Attention: $O(n\log n)$ Sparse Attention with Energy Decay for Long Video Generation(径向注意力:用于长视频生成的具有能量衰减的O(n log n)稀疏注意力机制)
[] 🤖 DiffuCoder: Understanding and Improving Masked Diffusion Models for Code Generation(DiffuCoder:理解并改进用于代码生成的掩码扩散模型)
[] 🧠 HumanOmniV2: From Understanding to Omni-Modal Reasoning with Context(HumanOmniV2:基于上下文理解到全模态推理)
[] 🧠 Thinking Beyond Tokens: From Brain-Inspired Intelligence to Cognitive Foundations for Artificial General Intelligence and its Societal Impact(超越Token:从脑启发智能到通用人工智能的认知基础及其社会影响)
[] 💡 Data Efficacy for Language Model Training(语言模型训练中的数据效能)
[] 🎬 FreeLong++: Training-Free Long Video Generation via Multi-band SpectralFusion(FreeLong++:通过多频段频谱融合实现免训练长视频生成)
[] 🖼 IR3D-Bench: Evaluating Vision-Language Model Scene Understanding as Agentic Inverse Rendering(IR3D-Bench:评估视觉-语言模型作为智能体进行逆向渲染的场景理解能力)
[] 🛡 Peccavi: Visual Paraphrase Attack Safe and Distortion Free Image Watermarking Technique for AI-Generated Images(Peccavi:一种针对AI生成图像的视觉释义攻击安全且无失真的图像水印技术)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 7 月 3 日 · 9 分钟
本期的 12 篇论文如下:
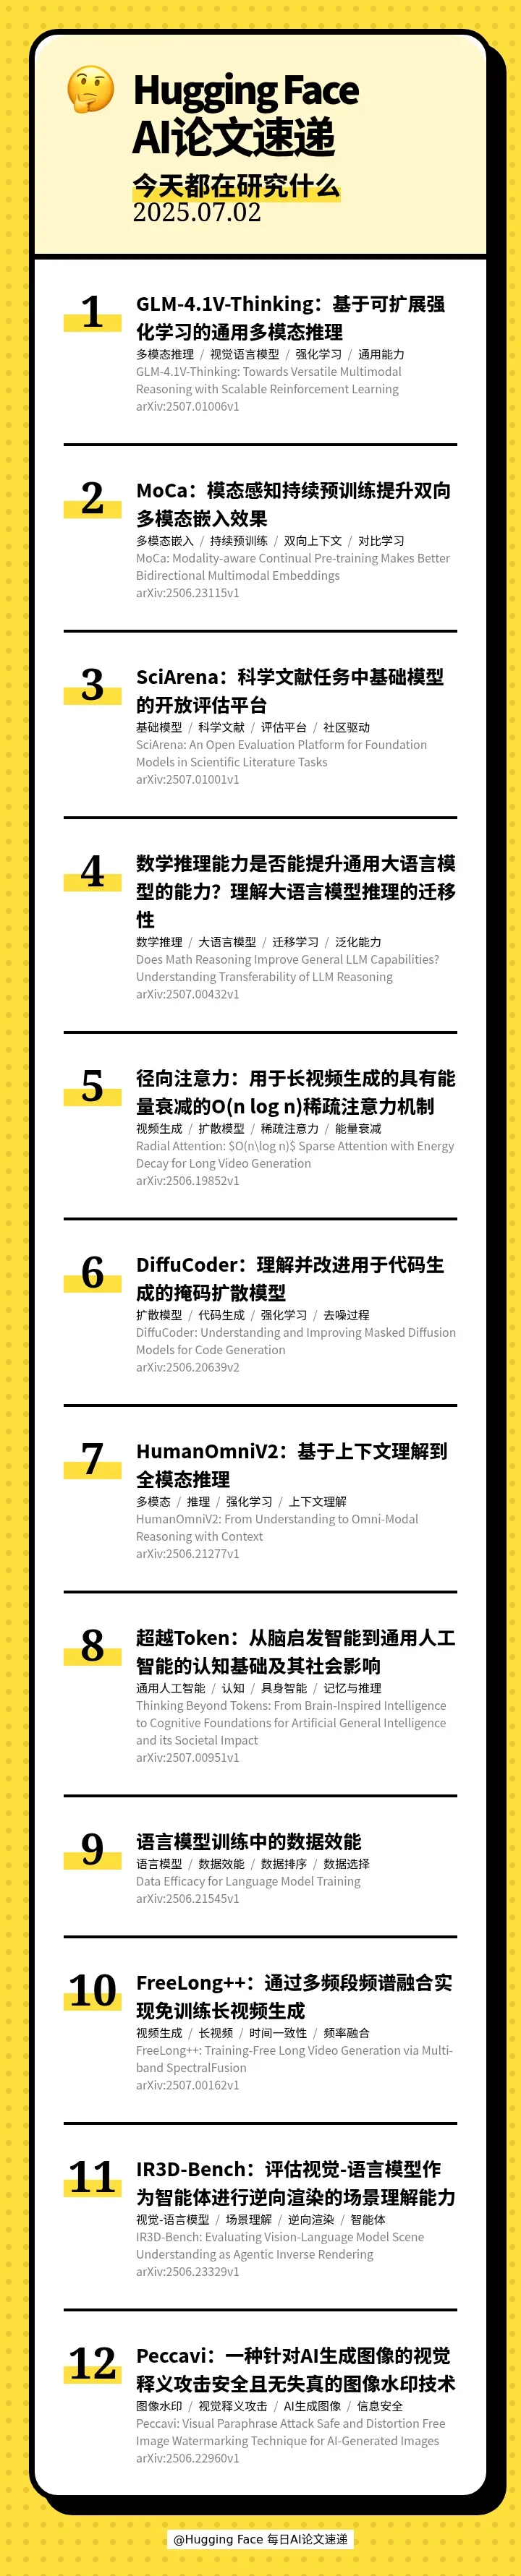
[] 💡 GLM-4.1V-Thinking: Towards Versatile Multimodal Reasoning with Scalable Reinforcement Learning(GLM-4.1V-Thinking:基于可扩展强化学习的通用多模态推理)
[] 🖼 MoCa: Modality-aware Continual Pre-training Makes Better Bidirectional Multimodal Embeddings(MoCa:模态感知持续预训练提升双向多模态嵌入效果)
[] 🔬 SciArena: An Open Evaluation Platform for Foundation Models in Scientific Literature Tasks(SciArena:科学文献任务中基础模型的开放评估平台)
[] 🤔 Does Math Reasoning Improve General LLM Capabilities? Understanding Transferability of LLM Reasoning(数学推理能力是否能提升通用大语言模型的能力?理解大语言模型推理的迁移性)
[] 🎬 Radial Attention: $O(n\log n)$ Sparse Attention with Energy Decay for Long Video Generation(径向注意力:用于长视频生成的具有能量衰减的O(n log n)稀疏注意力机制)
[] 🤖 DiffuCoder: Understanding and Improving Masked Diffusion Models for Code Generation(DiffuCoder:理解并改进用于代码生成的掩码扩散模型)
[] 🧠 HumanOmniV2: From Understanding to Omni-Modal Reasoning with Context(HumanOmniV2:基于上下文理解到全模态推理)
[] 🧠 Thinking Beyond Tokens: From Brain-Inspired Intelligence to Cognitive Foundations for Artificial General Intelligence and its Societal Impact(超越Token:从脑启发智能到通用人工智能的认知基础及其社会影响)
[] 💡 Data Efficacy for Language Model Training(语言模型训练中的数据效能)
[] 🎬 FreeLong++: Training-Free Long Video Generation via Multi-band SpectralFusion(FreeLong++:通过多频段频谱融合实现免训练长视频生成)
[] 🖼 IR3D-Bench: Evaluating Vision-Language Model Scene Understanding as Agentic Inverse Rendering(IR3D-Bench:评估视觉-语言模型作为智能体进行逆向渲染的场景理解能力)
[] 🛡 Peccavi: Visual Paraphrase Attack Safe and Distortion Free Image Watermarking Technique for AI-Generated Images(Peccavi:一种针对AI生成图像的视觉释义攻击安全且无失真的图像水印技术)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟