H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

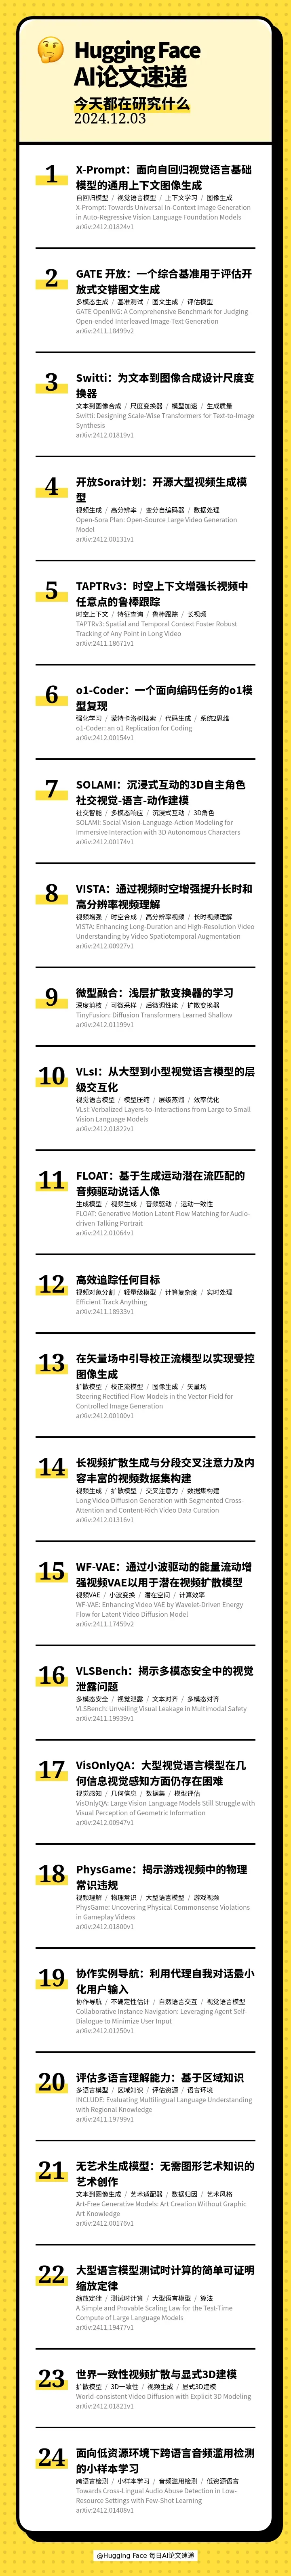
本期的 24 篇论文如下:
[] 🖼 X-Prompt: Towards Universal In-Context Image Generation in Auto-Regressive Vision Language Foundation Models(X-Prompt:面向自回归视觉语言基础模型的通用上下文图像生成)
[] 📊 GATE OpenING: A Comprehensive Benchmark for Judging Open-ended Interleaved Image-Text Generation(GATE 开放:一个综合基准用于评估开放式交错图文生成)
[] 🖼 Switti: Designing Scale-Wise Transformers for Text-to-Image Synthesis(Switti:为文本到图像合成设计尺度变换器)
[] 🎥 Open-Sora Plan: Open-Source Large Video Generation Model(开放Sora计划:开源大型视频生成模型)
[] 🎥 TAPTRv3: Spatial and Temporal Context Foster Robust Tracking of Any Point in Long Video(TAPTRv3:时空上下文增强长视频中任意点的鲁棒跟踪)
[] 🤖 o1-Coder: an o1 Replication for Coding(o1-Coder:一个面向编码任务的o1模型复现)
[] 🤖 SOLAMI: Social Vision-Language-Action Modeling for Immersive Interaction with 3D Autonomous Characters(SOLAMI:沉浸式互动的3D自主角色社交视觉-语言-动作建模)
[] 🎥 VISTA: Enhancing Long-Duration and High-Resolution Video Understanding by Video Spatiotemporal Augmentation(VISTA:通过视频时空增强提升长时和高分辨率视频理解)
[] 🔍 TinyFusion: Diffusion Transformers Learned Shallow(微型融合:浅层扩散变换器的学习)
[] 🔍 VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models(VLsI:从大型到小型视觉语言模型的层级交互化)
[] 🎙 FLOAT: Generative Motion Latent Flow Matching for Audio-driven Talking Portrait(FLOAT:基于生成运动潜在流匹配的音频驱动说话人像)
[] 🚀 Efficient Track Anything(高效追踪任何目标)
[] 🌊 Steering Rectified Flow Models in the Vector Field for Controlled Image Generation(在矢量场中引导校正流模型以实现受控图像生成)
[] 🎥 Long Video Diffusion Generation with Segmented Cross-Attention and Content-Rich Video Data Curation(长视频扩散生成与分段交叉注意力及内容丰富的视频数据集构建)
[] 📹 WF-VAE: Enhancing Video VAE by Wavelet-Driven Energy Flow for Latent Video Diffusion Model(WF-VAE:通过小波驱动的能量流动增强视频VAE以用于潜在视频扩散模型)
[] 🔍 VLSBench: Unveiling Visual Leakage in Multimodal Safety(VLSBench:揭示多模态安全中的视觉泄露问题)
[] 🧠 VisOnlyQA: Large Vision Language Models Still Struggle with Visual Perception of Geometric Information(VisOnlyQA:大型视觉语言模型在几何信息视觉感知方面仍存在困难)
[] 🎮 PhysGame: Uncovering Physical Commonsense Violations in Gameplay Videos(PhysGame:揭示游戏视频中的物理常识违规)
[] 🗣 Collaborative Instance Navigation: Leveraging Agent Self-Dialogue to Minimize User Input(协作实例导航:利用代理自我对话最小化用户输入)
[] 🌍 INCLUDE: Evaluating Multilingual Language Understanding with Regional Knowledge(评估多语言理解能力:基于区域知识)
[] 🎨 Art-Free Generative Models: Art Creation Without Graphic Art Knowledge(无艺术生成模型:无需图形艺术知识的艺术创作)
[] 📈 A Simple and Provable Scaling Law for the Test-Time Compute of Large Language Models(大型语言模型测试时计算的简单可证明缩放定律)
[] 🌐 World-consistent Video Diffusion with Explicit 3D Modeling(世界一致性视频扩散与显式3D建模)
[] 🔊 Towards Cross-Lingual Audio Abuse Detection in Low-Resource Settings with Few-Shot Learning(面向低资源环境下跨语言音频滥用检测的小样本学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 12 月 4 日 · 17 分钟
本期的 24 篇论文如下:
[] 🖼 X-Prompt: Towards Universal In-Context Image Generation in Auto-Regressive Vision Language Foundation Models(X-Prompt:面向自回归视觉语言基础模型的通用上下文图像生成)
[] 📊 GATE OpenING: A Comprehensive Benchmark for Judging Open-ended Interleaved Image-Text Generation(GATE 开放:一个综合基准用于评估开放式交错图文生成)
[] 🖼 Switti: Designing Scale-Wise Transformers for Text-to-Image Synthesis(Switti:为文本到图像合成设计尺度变换器)
[] 🎥 Open-Sora Plan: Open-Source Large Video Generation Model(开放Sora计划:开源大型视频生成模型)
[] 🎥 TAPTRv3: Spatial and Temporal Context Foster Robust Tracking of Any Point in Long Video(TAPTRv3:时空上下文增强长视频中任意点的鲁棒跟踪)
[] 🤖 o1-Coder: an o1 Replication for Coding(o1-Coder:一个面向编码任务的o1模型复现)
[] 🤖 SOLAMI: Social Vision-Language-Action Modeling for Immersive Interaction with 3D Autonomous Characters(SOLAMI:沉浸式互动的3D自主角色社交视觉-语言-动作建模)
[] 🎥 VISTA: Enhancing Long-Duration and High-Resolution Video Understanding by Video Spatiotemporal Augmentation(VISTA:通过视频时空增强提升长时和高分辨率视频理解)
[] 🔍 TinyFusion: Diffusion Transformers Learned Shallow(微型融合:浅层扩散变换器的学习)
[] 🔍 VLsI: Verbalized Layers-to-Interactions from Large to Small Vision Language Models(VLsI:从大型到小型视觉语言模型的层级交互化)
[] 🎙 FLOAT: Generative Motion Latent Flow Matching for Audio-driven Talking Portrait(FLOAT:基于生成运动潜在流匹配的音频驱动说话人像)
[] 🚀 Efficient Track Anything(高效追踪任何目标)
[] 🌊 Steering Rectified Flow Models in the Vector Field for Controlled Image Generation(在矢量场中引导校正流模型以实现受控图像生成)
[] 🎥 Long Video Diffusion Generation with Segmented Cross-Attention and Content-Rich Video Data Curation(长视频扩散生成与分段交叉注意力及内容丰富的视频数据集构建)
[] 📹 WF-VAE: Enhancing Video VAE by Wavelet-Driven Energy Flow for Latent Video Diffusion Model(WF-VAE:通过小波驱动的能量流动增强视频VAE以用于潜在视频扩散模型)
[] 🔍 VLSBench: Unveiling Visual Leakage in Multimodal Safety(VLSBench:揭示多模态安全中的视觉泄露问题)
[] 🧠 VisOnlyQA: Large Vision Language Models Still Struggle with Visual Perception of Geometric Information(VisOnlyQA:大型视觉语言模型在几何信息视觉感知方面仍存在困难)
[] 🎮 PhysGame: Uncovering Physical Commonsense Violations in Gameplay Videos(PhysGame:揭示游戏视频中的物理常识违规)
[] 🗣 Collaborative Instance Navigation: Leveraging Agent Self-Dialogue to Minimize User Input(协作实例导航:利用代理自我对话最小化用户输入)
[] 🌍 INCLUDE: Evaluating Multilingual Language Understanding with Regional Knowledge(评估多语言理解能力:基于区域知识)
[] 🎨 Art-Free Generative Models: Art Creation Without Graphic Art Knowledge(无艺术生成模型:无需图形艺术知识的艺术创作)
[] 📈 A Simple and Provable Scaling Law for the Test-Time Compute of Large Language Models(大型语言模型测试时计算的简单可证明缩放定律)
[] 🌐 World-consistent Video Diffusion with Explicit 3D Modeling(世界一致性视频扩散与显式3D建模)
[] 🔊 Towards Cross-Lingual Audio Abuse Detection in Low-Resource Settings with Few-Shot Learning(面向低资源环境下跨语言音频滥用检测的小样本学习)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟