H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

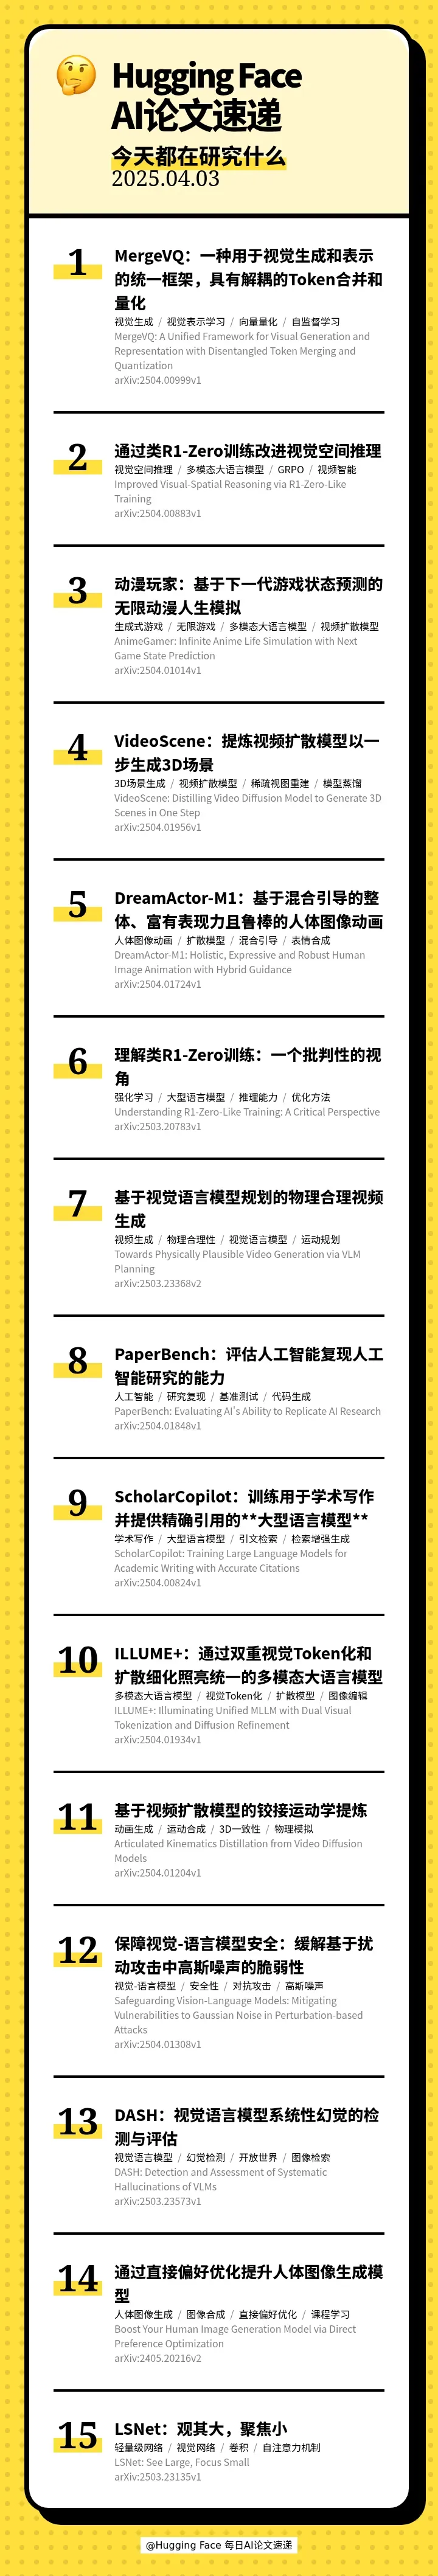
本期的 15 篇论文如下:
[] 🎨 MergeVQ: A Unified Framework for Visual Generation and Representation with Disentangled Token Merging and Quantization(MergeVQ:一种用于视觉生成和表示的统一框架,具有解耦的Token合并和量化)
[] 🧠 Improved Visual-Spatial Reasoning via R1-Zero-Like Training(通过类R1-Zero训练改进视觉空间推理)
[] 🎮 AnimeGamer: Infinite Anime Life Simulation with Next Game State Prediction(动漫玩家:基于下一代游戏状态预测的无限动漫人生模拟)
[] 🎬 VideoScene: Distilling Video Diffusion Model to Generate 3D Scenes in One Step(VideoScene:提炼视频扩散模型以一步生成3D场景)
[] 🎭 DreamActor-M1: Holistic, Expressive and Robust Human Image Animation with Hybrid Guidance(DreamActor-M1:基于混合引导的整体、富有表现力且鲁棒的人体图像动画)
[] 🧐 Understanding R1-Zero-Like Training: A Critical Perspective(理解类R1-Zero训练:一个批判性的视角)
[] 🎬 Towards Physically Plausible Video Generation via VLM Planning(基于视觉语言模型规划的物理合理视频生成)
[] 🤖 PaperBench: Evaluating AI's Ability to Replicate AI Research(PaperBench:评估人工智能复现人工智能研究的能力)
[] 🤖 ScholarCopilot: Training Large Language Models for Academic Writing with Accurate Citations(ScholarCopilot:训练用于学术写作并提供精确引用的**大型语言模型**)
[] 💡 ILLUME+: Illuminating Unified MLLM with Dual Visual Tokenization and Diffusion Refinement(ILLUME+:通过双重视觉Token化和扩散细化照亮统一的多模态大语言模型)
[] 💃 Articulated Kinematics Distillation from Video Diffusion Models(基于视频扩散模型的铰接运动学提炼)
[] 🛡 Safeguarding Vision-Language Models: Mitigating Vulnerabilities to Gaussian Noise in Perturbation-based Attacks(保障视觉-语言模型安全:缓解基于扰动攻击中高斯噪声的脆弱性)
[] 👁 DASH: Detection and Assessment of Systematic Hallucinations of VLMs(DASH:视觉语言模型系统性幻觉的检测与评估)
[] 🖼 Boost Your Human Image Generation Model via Direct Preference Optimization(通过直接偏好优化提升人体图像生成模型)
[] 👁 LSNet: See Large, Focus Small(LSNet:观其大,聚焦小)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 4 月 4 日 · 11 分钟
本期的 15 篇论文如下:
[] 🎨 MergeVQ: A Unified Framework for Visual Generation and Representation with Disentangled Token Merging and Quantization(MergeVQ:一种用于视觉生成和表示的统一框架,具有解耦的Token合并和量化)
[] 🧠 Improved Visual-Spatial Reasoning via R1-Zero-Like Training(通过类R1-Zero训练改进视觉空间推理)
[] 🎮 AnimeGamer: Infinite Anime Life Simulation with Next Game State Prediction(动漫玩家:基于下一代游戏状态预测的无限动漫人生模拟)
[] 🎬 VideoScene: Distilling Video Diffusion Model to Generate 3D Scenes in One Step(VideoScene:提炼视频扩散模型以一步生成3D场景)
[] 🎭 DreamActor-M1: Holistic, Expressive and Robust Human Image Animation with Hybrid Guidance(DreamActor-M1:基于混合引导的整体、富有表现力且鲁棒的人体图像动画)
[] 🧐 Understanding R1-Zero-Like Training: A Critical Perspective(理解类R1-Zero训练:一个批判性的视角)
[] 🎬 Towards Physically Plausible Video Generation via VLM Planning(基于视觉语言模型规划的物理合理视频生成)
[] 🤖 PaperBench: Evaluating AI's Ability to Replicate AI Research(PaperBench:评估人工智能复现人工智能研究的能力)
[] 🤖 ScholarCopilot: Training Large Language Models for Academic Writing with Accurate Citations(ScholarCopilot:训练用于学术写作并提供精确引用的**大型语言模型**)
[] 💡 ILLUME+: Illuminating Unified MLLM with Dual Visual Tokenization and Diffusion Refinement(ILLUME+:通过双重视觉Token化和扩散细化照亮统一的多模态大语言模型)
[] 💃 Articulated Kinematics Distillation from Video Diffusion Models(基于视频扩散模型的铰接运动学提炼)
[] 🛡 Safeguarding Vision-Language Models: Mitigating Vulnerabilities to Gaussian Noise in Perturbation-based Attacks(保障视觉-语言模型安全:缓解基于扰动攻击中高斯噪声的脆弱性)
[] 👁 DASH: Detection and Assessment of Systematic Hallucinations of VLMs(DASH:视觉语言模型系统性幻觉的检测与评估)
[] 🖼 Boost Your Human Image Generation Model via Direct Preference Optimization(通过直接偏好优化提升人体图像生成模型)
[] 👁 LSNet: See Large, Focus Small(LSNet:观其大,聚焦小)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟