H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
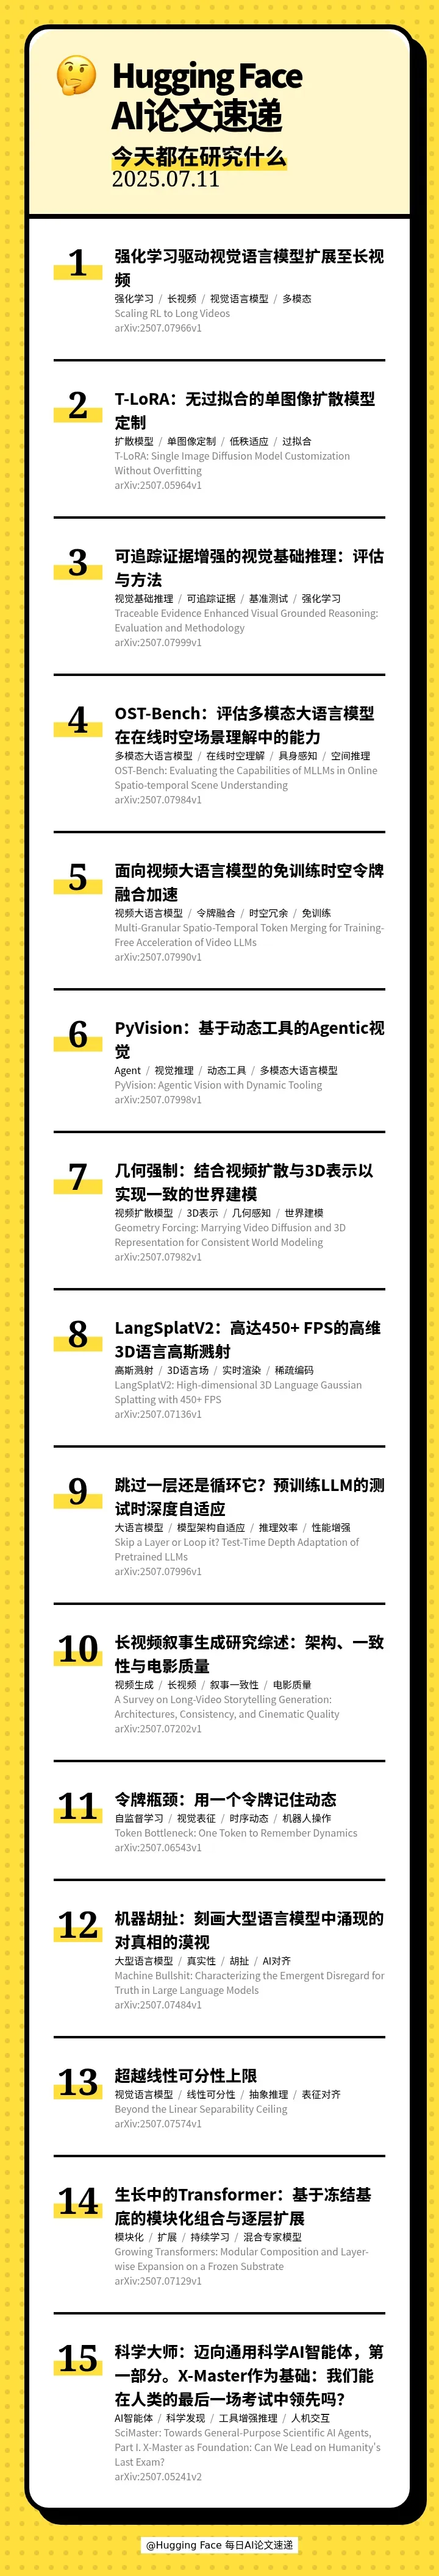
[] 🎬 Scaling RL to Long Videos(强化学习驱动视觉语言模型扩展至长视频)
[] 🖼 T-LoRA: Single Image Diffusion Model Customization Without Overfitting(T-LoRA:无过拟合的单图像扩散模型定制)
[] 🖼 Traceable Evidence Enhanced Visual Grounded Reasoning: Evaluation and Methodology(可追踪证据增强的视觉基础推理:评估与方法)
[] 🤖 OST-Bench: Evaluating the Capabilities of MLLMs in Online Spatio-temporal Scene Understanding(OST-Bench:评估多模态大语言模型在在线时空场景理解中的能力)
[] 🎬 Multi-Granular Spatio-Temporal Token Merging for Training-Free Acceleration of Video LLMs(面向视频大语言模型的免训练时空令牌融合加速)
[] 🤖 PyVision: Agentic Vision with Dynamic Tooling(PyVision:基于动态工具的Agentic视觉)
[] 🎬 Geometry Forcing: Marrying Video Diffusion and 3D Representation for Consistent World Modeling(几何强制:结合视频扩散与3D表示以实现一致的世界建模)
[] 🚀 LangSplatV2: High-dimensional 3D Language Gaussian Splatting with 450+ FPS(LangSplatV2:高达450+ FPS的高维3D语言高斯溅射)
[] 🧠 Skip a Layer or Loop it? Test-Time Depth Adaptation of Pretrained LLMs(跳过一层还是循环它?预训练LLM的测试时深度自适应)
[] 🎬 A Survey on Long-Video Storytelling Generation: Architectures, Consistency, and Cinematic Quality(长视频叙事生成研究综述:架构、一致性与电影质量)
[] 🤖 Token Bottleneck: One Token to Remember Dynamics(令牌瓶颈:用一个令牌记住动态)
[] 🤥 Machine Bullshit: Characterizing the Emergent Disregard for Truth in Large Language Models(机器胡扯:刻画大型语言模型中涌现的对真相的漠视)
[] 🧠 Beyond the Linear Separability Ceiling(超越线性可分性上限)
[] 🌱 Growing Transformers: Modular Composition and Layer-wise Expansion on a Frozen Substrate(生长中的Transformer:基于冻结基底的模块化组合与逐层扩展)
[] 🧪 SciMaster: Towards General-Purpose Scientific AI Agents, Part I. X-Master as Foundation: Can We Lead on Humanity's Last Exam?(科学大师:迈向通用科学AI智能体,第一部分。X-Master作为基础:我们能在人类的最后一场考试中领先吗?)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 7 月 12 日 · 11 分钟
本期的 15 篇论文如下:
[] 🎬 Scaling RL to Long Videos(强化学习驱动视觉语言模型扩展至长视频)
[] 🖼 T-LoRA: Single Image Diffusion Model Customization Without Overfitting(T-LoRA:无过拟合的单图像扩散模型定制)
[] 🖼 Traceable Evidence Enhanced Visual Grounded Reasoning: Evaluation and Methodology(可追踪证据增强的视觉基础推理:评估与方法)
[] 🤖 OST-Bench: Evaluating the Capabilities of MLLMs in Online Spatio-temporal Scene Understanding(OST-Bench:评估多模态大语言模型在在线时空场景理解中的能力)
[] 🎬 Multi-Granular Spatio-Temporal Token Merging for Training-Free Acceleration of Video LLMs(面向视频大语言模型的免训练时空令牌融合加速)
[] 🤖 PyVision: Agentic Vision with Dynamic Tooling(PyVision:基于动态工具的Agentic视觉)
[] 🎬 Geometry Forcing: Marrying Video Diffusion and 3D Representation for Consistent World Modeling(几何强制:结合视频扩散与3D表示以实现一致的世界建模)
[] 🚀 LangSplatV2: High-dimensional 3D Language Gaussian Splatting with 450+ FPS(LangSplatV2:高达450+ FPS的高维3D语言高斯溅射)
[] 🧠 Skip a Layer or Loop it? Test-Time Depth Adaptation of Pretrained LLMs(跳过一层还是循环它?预训练LLM的测试时深度自适应)
[] 🎬 A Survey on Long-Video Storytelling Generation: Architectures, Consistency, and Cinematic Quality(长视频叙事生成研究综述:架构、一致性与电影质量)
[] 🤖 Token Bottleneck: One Token to Remember Dynamics(令牌瓶颈:用一个令牌记住动态)
[] 🤥 Machine Bullshit: Characterizing the Emergent Disregard for Truth in Large Language Models(机器胡扯:刻画大型语言模型中涌现的对真相的漠视)
[] 🧠 Beyond the Linear Separability Ceiling(超越线性可分性上限)
[] 🌱 Growing Transformers: Modular Composition and Layer-wise Expansion on a Frozen Substrate(生长中的Transformer:基于冻结基底的模块化组合与逐层扩展)
[] 🧪 SciMaster: Towards General-Purpose Scientific AI Agents, Part I. X-Master as Foundation: Can We Lead on Humanity's Last Exam?(科学大师:迈向通用科学AI智能体,第一部分。X-Master作为基础:我们能在人类的最后一场考试中领先吗?)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟