H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
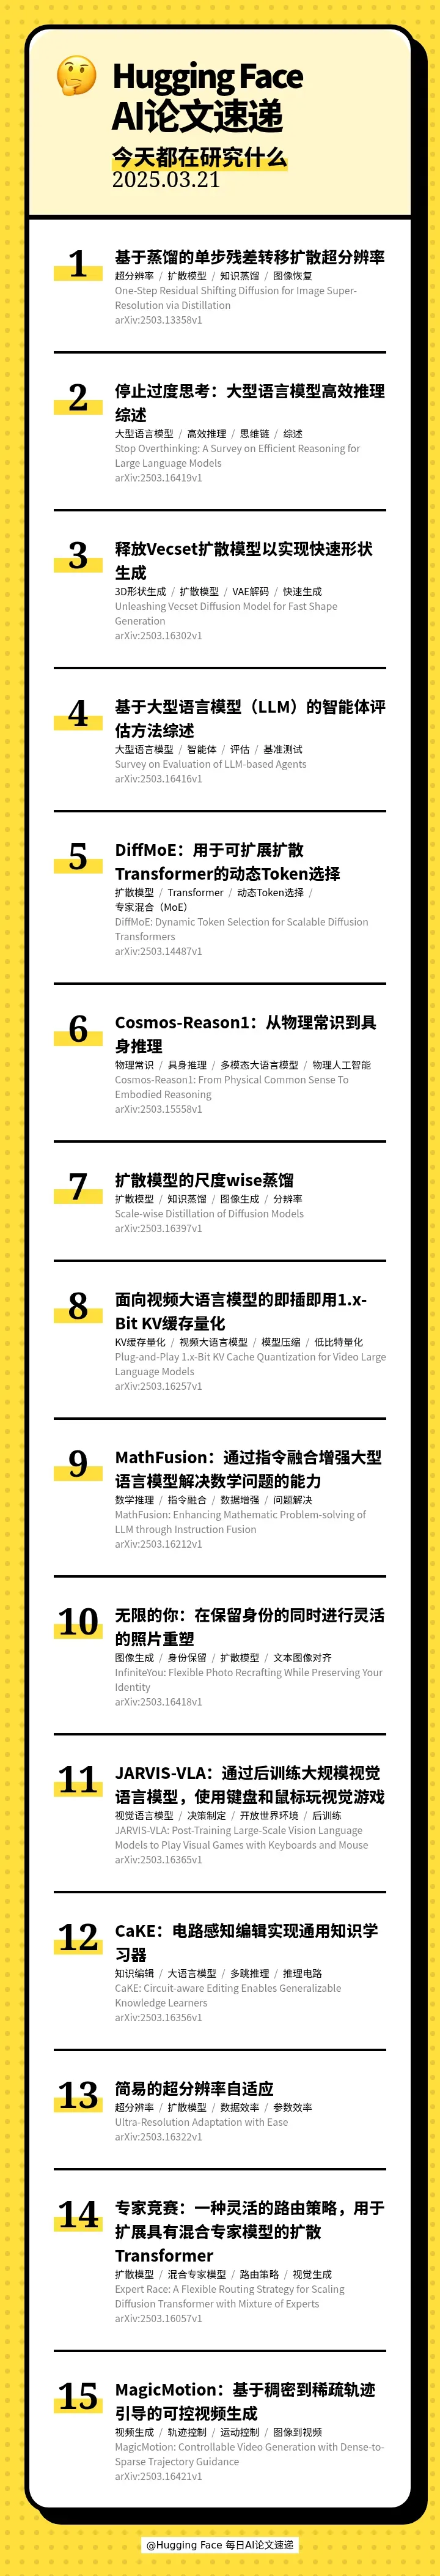
[] 🖼 One-Step Residual Shifting Diffusion for Image Super-Resolution via Distillation(基于蒸馏的单步残差转移扩散超分辨率)
[] 🤔 Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models(停止过度思考:大型语言模型高效推理综述)
[] 🚀 Unleashing Vecset Diffusion Model for Fast Shape Generation(释放Vecset扩散模型以实现快速形状生成)
[] 🤖 Survey on Evaluation of LLM-based Agents(基于大型语言模型(LLM)的智能体评估方法综述)
[] 🎨 DiffMoE: Dynamic Token Selection for Scalable Diffusion Transformers(DiffMoE:用于可扩展扩散Transformer的动态Token选择)
[] 🤖 Cosmos-Reason1: From Physical Common Sense To Embodied Reasoning(Cosmos-Reason1:从物理常识到具身推理)
[] 🖼 Scale-wise Distillation of Diffusion Models(扩散模型的尺度wise蒸馏)
[] 🗜 Plug-and-Play 1.x-Bit KV Cache Quantization for Video Large Language Models(面向视频大语言模型的即插即用1.x-Bit KV缓存量化)
[] 🧮 MathFusion: Enhancing Mathematic Problem-solving of LLM through Instruction Fusion(MathFusion:通过指令融合增强大型语言模型解决数学问题的能力)
[] 🖼 InfiniteYou: Flexible Photo Recrafting While Preserving Your Identity(无限的你:在保留身份的同时进行灵活的照片重塑)
[] 🎮 JARVIS-VLA: Post-Training Large-Scale Vision Language Models to Play Visual Games with Keyboards and Mouse(JARVIS-VLA:通过后训练大规模视觉语言模型,使用键盘和鼠标玩视觉游戏)
[] 🧠 CaKE: Circuit-aware Editing Enables Generalizable Knowledge Learners(CaKE:电路感知编辑实现通用知识学习器)
[] 🖼 Ultra-Resolution Adaptation with Ease(简易的超分辨率自适应)
[] 🎨 Expert Race: A Flexible Routing Strategy for Scaling Diffusion Transformer with Mixture of Experts(专家竞赛:一种灵活的路由策略,用于扩展具有混合专家模型的扩散Transformer)
[] 🎬 MagicMotion: Controllable Video Generation with Dense-to-Sparse Trajectory Guidance(MagicMotion:基于稠密到稀疏轨迹引导的可控视频生成)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 3 月 22 日 · 11 分钟
本期的 15 篇论文如下:
[] 🖼 One-Step Residual Shifting Diffusion for Image Super-Resolution via Distillation(基于蒸馏的单步残差转移扩散超分辨率)
[] 🤔 Stop Overthinking: A Survey on Efficient Reasoning for Large Language Models(停止过度思考:大型语言模型高效推理综述)
[] 🚀 Unleashing Vecset Diffusion Model for Fast Shape Generation(释放Vecset扩散模型以实现快速形状生成)
[] 🤖 Survey on Evaluation of LLM-based Agents(基于大型语言模型(LLM)的智能体评估方法综述)
[] 🎨 DiffMoE: Dynamic Token Selection for Scalable Diffusion Transformers(DiffMoE:用于可扩展扩散Transformer的动态Token选择)
[] 🤖 Cosmos-Reason1: From Physical Common Sense To Embodied Reasoning(Cosmos-Reason1:从物理常识到具身推理)
[] 🖼 Scale-wise Distillation of Diffusion Models(扩散模型的尺度wise蒸馏)
[] 🗜 Plug-and-Play 1.x-Bit KV Cache Quantization for Video Large Language Models(面向视频大语言模型的即插即用1.x-Bit KV缓存量化)
[] 🧮 MathFusion: Enhancing Mathematic Problem-solving of LLM through Instruction Fusion(MathFusion:通过指令融合增强大型语言模型解决数学问题的能力)
[] 🖼 InfiniteYou: Flexible Photo Recrafting While Preserving Your Identity(无限的你:在保留身份的同时进行灵活的照片重塑)
[] 🎮 JARVIS-VLA: Post-Training Large-Scale Vision Language Models to Play Visual Games with Keyboards and Mouse(JARVIS-VLA:通过后训练大规模视觉语言模型,使用键盘和鼠标玩视觉游戏)
[] 🧠 CaKE: Circuit-aware Editing Enables Generalizable Knowledge Learners(CaKE:电路感知编辑实现通用知识学习器)
[] 🖼 Ultra-Resolution Adaptation with Ease(简易的超分辨率自适应)
[] 🎨 Expert Race: A Flexible Routing Strategy for Scaling Diffusion Transformer with Mixture of Experts(专家竞赛:一种灵活的路由策略,用于扩展具有混合专家模型的扩散Transformer)
[] 🎬 MagicMotion: Controllable Video Generation with Dense-to-Sparse Trajectory Guidance(MagicMotion:基于稠密到稀疏轨迹引导的可控视频生成)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟