H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【目录】
本期的 15 篇论文如下:
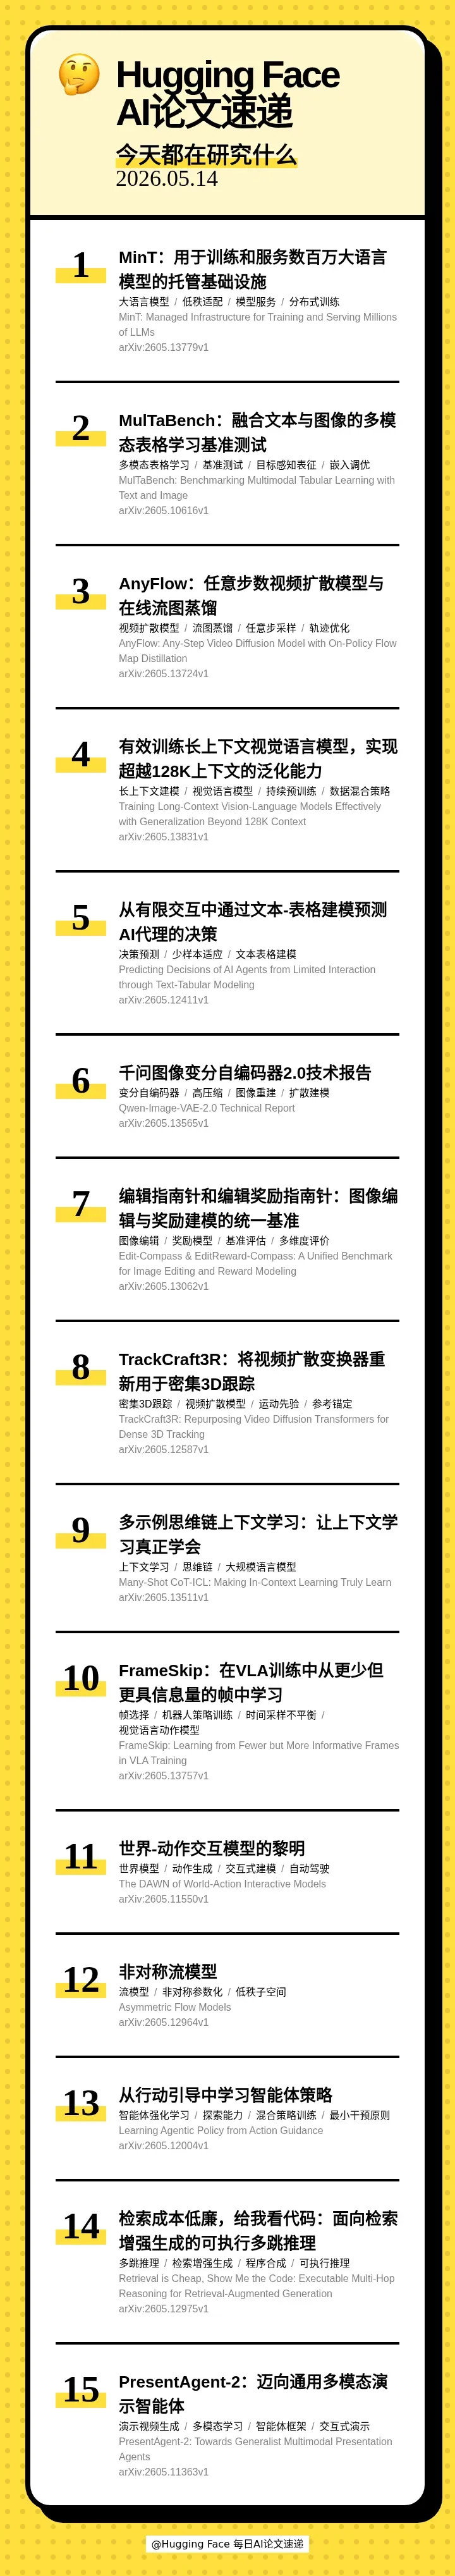
[] 🏗 MinT: Managed Infrastructure for Training and Serving Millions of LLMs(MinT:用于训练和服务数百万大语言模型的托管基础设施)
[] 📊 MulTaBench: Benchmarking Multimodal Tabular Learning with Text and Image(MulTaBench:融合文本与图像的多模态表格学习基准测试)
[] 🎬 AnyFlow: Any-Step Video Diffusion Model with On-Policy Flow Map Distillation(AnyFlow:任意步数视频扩散模型与在线流图蒸馏)
[] 📚 Training Long-Context Vision-Language Models Effectively with Generalization Beyond 128K Context(有效训练长上下文视觉语言模型,实现超越128K上下文的泛化能力)
[] 🤖 Predicting Decisions of AI Agents from Limited Interaction through Text-Tabular Modeling(从有限交互中通过文本-表格建模预测AI代理的决策)
[] 🖼 Qwen-Image-VAE-2.0 Technical Report(千问图像变分自编码器2.0技术报告)
[] 🎨 Edit-Compass & EditReward-Compass: A Unified Benchmark for Image Editing and Reward Modeling(编辑指南针和编辑奖励指南针:图像编辑与奖励建模的统一基准)
[] 🎯 TrackCraft3R: Repurposing Video Diffusion Transformers for Dense 3D Tracking(TrackCraft3R:将视频扩散变换器重新用于密集3D跟踪)
[] 🧠 Many-Shot CoT-ICL: Making In-Context Learning Truly Learn(多示例思维链上下文学习:让上下文学习真正学会)
[] 🎯 FrameSkip: Learning from Fewer but More Informative Frames in VLA Training(FrameSkip:在VLA训练中从更少但更具信息量的帧中学习)
[] 🌅 The DAWN of World-Action Interactive Models(世界-动作交互模型的黎明)
[] 🌊 Asymmetric Flow Models(非对称流模型)
[] 🤖 Learning Agentic Policy from Action Guidance(从行动引导中学习智能体策略)
[] 💻 Retrieval is Cheap, Show Me the Code: Executable Multi-Hop Reasoning for Retrieval-Augmented Generation(检索成本低廉,给我看代码:面向检索增强生成的可执行多跳推理)
[] 🎬 PresentAgent-2: Towards Generalist Multimodal Presentation Agents(PresentAgent-2:迈向通用多模态演示智能体)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 5 月 15 日 · 13 分钟
【目录】
本期的 15 篇论文如下:
[] 🏗 MinT: Managed Infrastructure for Training and Serving Millions of LLMs(MinT:用于训练和服务数百万大语言模型的托管基础设施)
[] 📊 MulTaBench: Benchmarking Multimodal Tabular Learning with Text and Image(MulTaBench:融合文本与图像的多模态表格学习基准测试)
[] 🎬 AnyFlow: Any-Step Video Diffusion Model with On-Policy Flow Map Distillation(AnyFlow:任意步数视频扩散模型与在线流图蒸馏)
[] 📚 Training Long-Context Vision-Language Models Effectively with Generalization Beyond 128K Context(有效训练长上下文视觉语言模型,实现超越128K上下文的泛化能力)
[] 🤖 Predicting Decisions of AI Agents from Limited Interaction through Text-Tabular Modeling(从有限交互中通过文本-表格建模预测AI代理的决策)
[] 🖼 Qwen-Image-VAE-2.0 Technical Report(千问图像变分自编码器2.0技术报告)
[] 🎨 Edit-Compass & EditReward-Compass: A Unified Benchmark for Image Editing and Reward Modeling(编辑指南针和编辑奖励指南针:图像编辑与奖励建模的统一基准)
[] 🎯 TrackCraft3R: Repurposing Video Diffusion Transformers for Dense 3D Tracking(TrackCraft3R:将视频扩散变换器重新用于密集3D跟踪)
[] 🧠 Many-Shot CoT-ICL: Making In-Context Learning Truly Learn(多示例思维链上下文学习:让上下文学习真正学会)
[] 🎯 FrameSkip: Learning from Fewer but More Informative Frames in VLA Training(FrameSkip:在VLA训练中从更少但更具信息量的帧中学习)
[] 🌅 The DAWN of World-Action Interactive Models(世界-动作交互模型的黎明)
[] 🌊 Asymmetric Flow Models(非对称流模型)
[] 🤖 Learning Agentic Policy from Action Guidance(从行动引导中学习智能体策略)
[] 💻 Retrieval is Cheap, Show Me the Code: Executable Multi-Hop Reasoning for Retrieval-Augmented Generation(检索成本低廉,给我看代码:面向检索增强生成的可执行多跳推理)
[] 🎬 PresentAgent-2: Towards Generalist Multimodal Presentation Agents(PresentAgent-2:迈向通用多模态演示智能体)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟