H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

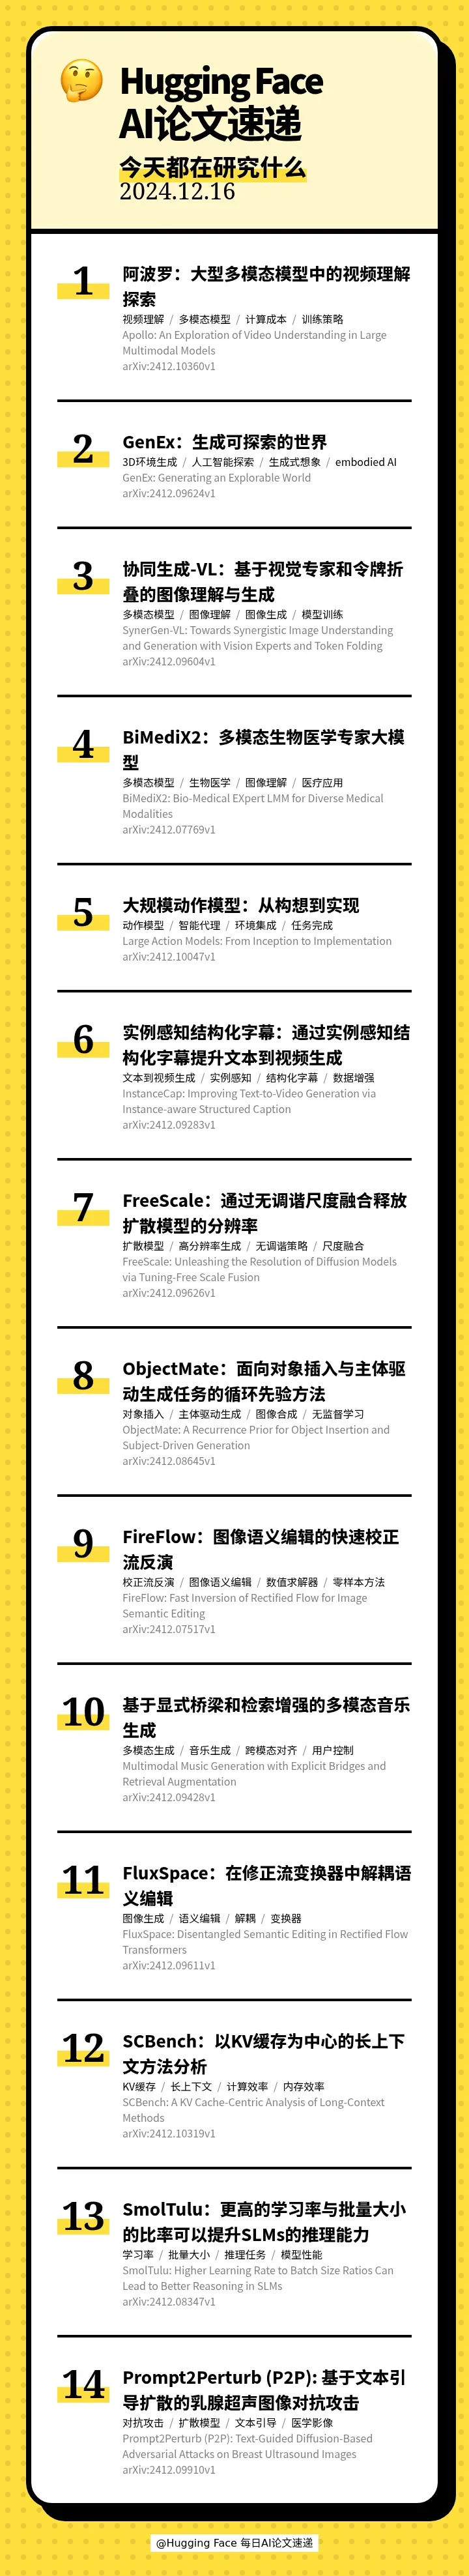
本期的 14 篇论文如下:
[] 🎥 Apollo: An Exploration of Video Understanding in Large Multimodal Models(阿波罗:大型多模态模型中的视频理解探索)
[] 🌍 GenEx: Generating an Explorable World(GenEx:生成可探索的世界)
[] 🌐 SynerGen-VL: Towards Synergistic Image Understanding and Generation with Vision Experts and Token Folding(协同生成-VL:基于视觉专家和令牌折叠的图像理解与生成)
[] 🩺 BiMediX2: Bio-Medical EXpert LMM for Diverse Medical Modalities(BiMediX2:多模态生物医学专家大模型)
[] 🤖 Large Action Models: From Inception to Implementation(大规模动作模型:从构想到实现)
[] 🎥 InstanceCap: Improving Text-to-Video Generation via Instance-aware Structured Caption(实例感知结构化字幕:通过实例感知结构化字幕提升文本到视频生成)
[] 🌟 FreeScale: Unleashing the Resolution of Diffusion Models via Tuning-Free Scale Fusion(FreeScale:通过无调谐尺度融合释放扩散模型的分辨率)
[] 🎯 ObjectMate: A Recurrence Prior for Object Insertion and Subject-Driven Generation(ObjectMate:面向对象插入与主体驱动生成任务的循环先验方法)
[] 🔥 FireFlow: Fast Inversion of Rectified Flow for Image Semantic Editing(FireFlow:图像语义编辑的快速校正流反演)
[] 🎵 Multimodal Music Generation with Explicit Bridges and Retrieval Augmentation(基于显式桥梁和检索增强的多模态音乐生成)
[] 🎨 FluxSpace: Disentangled Semantic Editing in Rectified Flow Transformers(FluxSpace:在修正流变换器中解耦语义编辑)
[] 📊 SCBench: A KV Cache-Centric Analysis of Long-Context Methods(SCBench:以KV缓存为中心的长上下文方法分析)
[] 🧠 SmolTulu: Higher Learning Rate to Batch Size Ratios Can Lead to Better Reasoning in SLMs(SmolTulu:更高的学习率与批量大小的比率可以提升SLMs的推理能力)
[] 🩺 Prompt2Perturb (P2P): Text-Guided Diffusion-Based Adversarial Attacks on Breast Ultrasound Images(Prompt2Perturb (P2P): 基于文本引导扩散的乳腺超声图像对抗攻击)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 12 月 17 日 · 11 分钟
本期的 14 篇论文如下:
[] 🎥 Apollo: An Exploration of Video Understanding in Large Multimodal Models(阿波罗:大型多模态模型中的视频理解探索)
[] 🌍 GenEx: Generating an Explorable World(GenEx:生成可探索的世界)
[] 🌐 SynerGen-VL: Towards Synergistic Image Understanding and Generation with Vision Experts and Token Folding(协同生成-VL:基于视觉专家和令牌折叠的图像理解与生成)
[] 🩺 BiMediX2: Bio-Medical EXpert LMM for Diverse Medical Modalities(BiMediX2:多模态生物医学专家大模型)
[] 🤖 Large Action Models: From Inception to Implementation(大规模动作模型:从构想到实现)
[] 🎥 InstanceCap: Improving Text-to-Video Generation via Instance-aware Structured Caption(实例感知结构化字幕:通过实例感知结构化字幕提升文本到视频生成)
[] 🌟 FreeScale: Unleashing the Resolution of Diffusion Models via Tuning-Free Scale Fusion(FreeScale:通过无调谐尺度融合释放扩散模型的分辨率)
[] 🎯 ObjectMate: A Recurrence Prior for Object Insertion and Subject-Driven Generation(ObjectMate:面向对象插入与主体驱动生成任务的循环先验方法)
[] 🔥 FireFlow: Fast Inversion of Rectified Flow for Image Semantic Editing(FireFlow:图像语义编辑的快速校正流反演)
[] 🎵 Multimodal Music Generation with Explicit Bridges and Retrieval Augmentation(基于显式桥梁和检索增强的多模态音乐生成)
[] 🎨 FluxSpace: Disentangled Semantic Editing in Rectified Flow Transformers(FluxSpace:在修正流变换器中解耦语义编辑)
[] 📊 SCBench: A KV Cache-Centric Analysis of Long-Context Methods(SCBench:以KV缓存为中心的长上下文方法分析)
[] 🧠 SmolTulu: Higher Learning Rate to Batch Size Ratios Can Lead to Better Reasoning in SLMs(SmolTulu:更高的学习率与批量大小的比率可以提升SLMs的推理能力)
[] 🩺 Prompt2Perturb (P2P): Text-Guided Diffusion-Based Adversarial Attacks on Breast Ultrasound Images(Prompt2Perturb (P2P): 基于文本引导扩散的乳腺超声图像对抗攻击)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟