H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
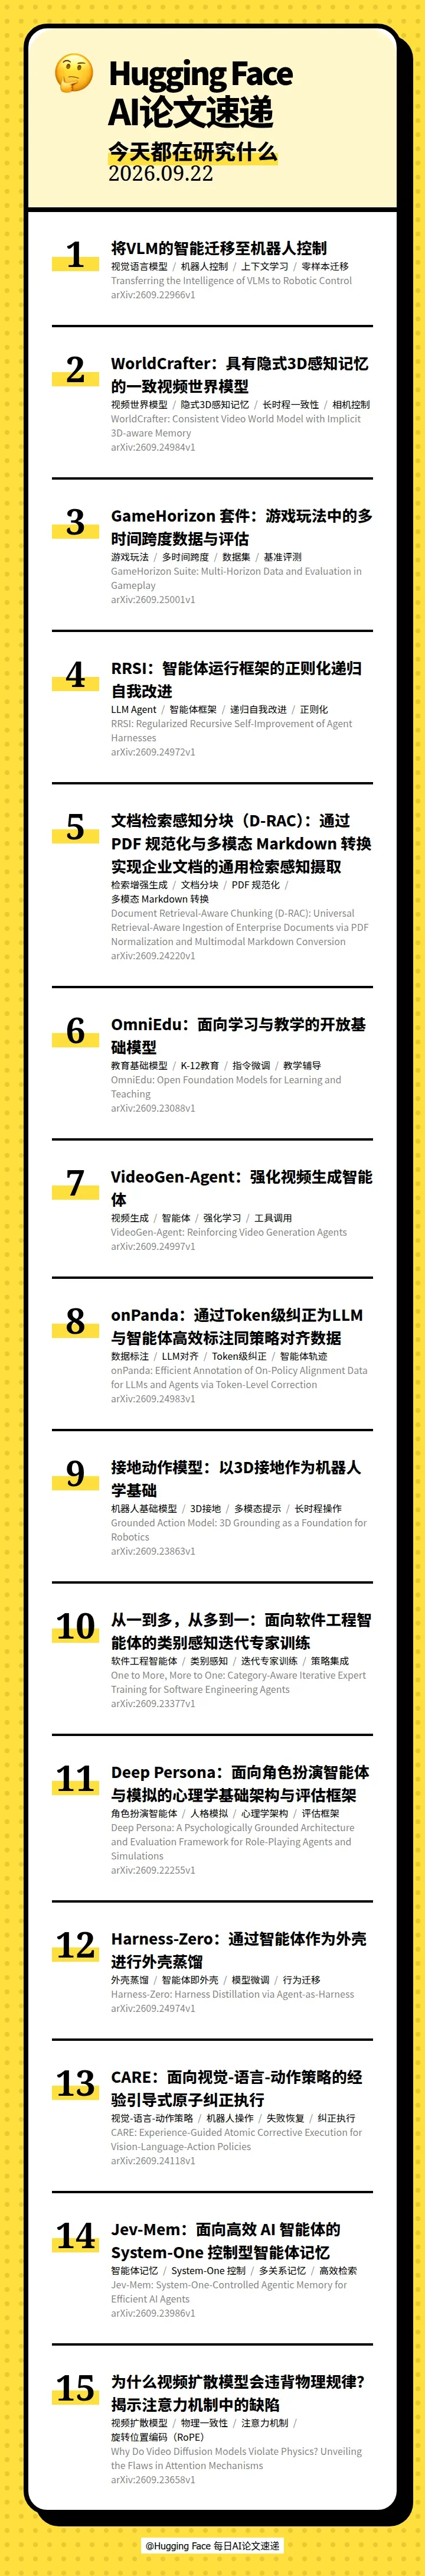
本期的 15 篇论文如下:
[] 🤖 Transferring the Intelligence of VLMs to Robotic Control(将VLM的智能迁移至机器人控制)
[] 🎥 WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory(WorldCrafter:具有隐式3D感知记忆的一致视频世界模型)
[] 🎮 GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay(GameHorizon 套件:游戏玩法中的多时间跨度数据与评估)
[] 🧬 RRSI: Regularized Recursive Self-Improvement of Agent Harnesses(RRSI:智能体运行框架的正则化递归自我改进)
[] 📄 Document Retrieval-Aware Chunking (D-RAC): Universal Retrieval-Aware Ingestion of Enterprise Documents via PDF Normalization and Multimodal Markdown Conversion(文档检索感知分块(D-RAC):通过 PDF 规范化与多模态 Markdown 转换实现企业文档的通用检索感知摄取)
[] 🎓 OmniEdu: Open Foundation Models for Learning and Teaching(OmniEdu:面向学习与教学的开放基础模型)
[] 🎬 VideoGen-Agent: Reinforcing Video Generation Agents(VideoGen-Agent:强化视频生成智能体)
[] 🐼 onPanda: Efficient Annotation of On-Policy Alignment Data for LLMs and Agents via Token-Level Correction(onPanda:通过Token级纠正为LLM与智能体高效标注同策略对齐数据)
[] 🤖 Grounded Action Model: 3D Grounding as a Foundation for Robotics(接地动作模型:以3D接地作为机器人学基础)
[] 🤖 One to More, More to One: Category-Aware Iterative Expert Training for Software Engineering Agents(从一到多,从多到一:面向软件工程智能体的类别感知迭代专家训练)
[] 🎭 Deep Persona: A Psychologically Grounded Architecture and Evaluation Framework for Role-Playing Agents and Simulations(Deep Persona:面向角色扮演智能体与模拟的心理学基础架构与评估框架)
[] 🧠 Harness-Zero: Harness Distillation via Agent-as-Harness(Harness-Zero:通过智能体作为外壳进行外壳蒸馏)
[] 🤖 CARE: Experience-Guided Atomic Corrective Execution for Vision-Language-Action Policies(CARE:面向视觉-语言-动作策略的经验引导式原子纠正执行)
[] 🧠 Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents(Jev-Mem:面向高效 AI 智能体的 System-One 控制型智能体记忆)
[] 🎥 Why Do Video Diffusion Models Violate Physics? Unveiling the Flaws in Attention Mechanisms(为什么视频扩散模型会违背物理规律?揭示注意力机制中的缺陷)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 9 月 23 日 · 12 分钟
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
[] 🤖 Transferring the Intelligence of VLMs to Robotic Control(将VLM的智能迁移至机器人控制)
[] 🎥 WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory(WorldCrafter:具有隐式3D感知记忆的一致视频世界模型)
[] 🎮 GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay(GameHorizon 套件:游戏玩法中的多时间跨度数据与评估)
[] 🧬 RRSI: Regularized Recursive Self-Improvement of Agent Harnesses(RRSI:智能体运行框架的正则化递归自我改进)
[] 📄 Document Retrieval-Aware Chunking (D-RAC): Universal Retrieval-Aware Ingestion of Enterprise Documents via PDF Normalization and Multimodal Markdown Conversion(文档检索感知分块(D-RAC):通过 PDF 规范化与多模态 Markdown 转换实现企业文档的通用检索感知摄取)
[] 🎓 OmniEdu: Open Foundation Models for Learning and Teaching(OmniEdu:面向学习与教学的开放基础模型)
[] 🎬 VideoGen-Agent: Reinforcing Video Generation Agents(VideoGen-Agent:强化视频生成智能体)
[] 🐼 onPanda: Efficient Annotation of On-Policy Alignment Data for LLMs and Agents via Token-Level Correction(onPanda:通过Token级纠正为LLM与智能体高效标注同策略对齐数据)
[] 🤖 Grounded Action Model: 3D Grounding as a Foundation for Robotics(接地动作模型:以3D接地作为机器人学基础)
[] 🤖 One to More, More to One: Category-Aware Iterative Expert Training for Software Engineering Agents(从一到多,从多到一:面向软件工程智能体的类别感知迭代专家训练)
[] 🎭 Deep Persona: A Psychologically Grounded Architecture and Evaluation Framework for Role-Playing Agents and Simulations(Deep Persona:面向角色扮演智能体与模拟的心理学基础架构与评估框架)
[] 🧠 Harness-Zero: Harness Distillation via Agent-as-Harness(Harness-Zero:通过智能体作为外壳进行外壳蒸馏)
[] 🤖 CARE: Experience-Guided Atomic Corrective Execution for Vision-Language-Action Policies(CARE:面向视觉-语言-动作策略的经验引导式原子纠正执行)
[] 🧠 Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents(Jev-Mem:面向高效 AI 智能体的 System-One 控制型智能体记忆)
[] 🎥 Why Do Video Diffusion Models Violate Physics? Unveiling the Flaws in Attention Mechanisms(为什么视频扩散模型会违背物理规律?揭示注意力机制中的缺陷)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟