H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

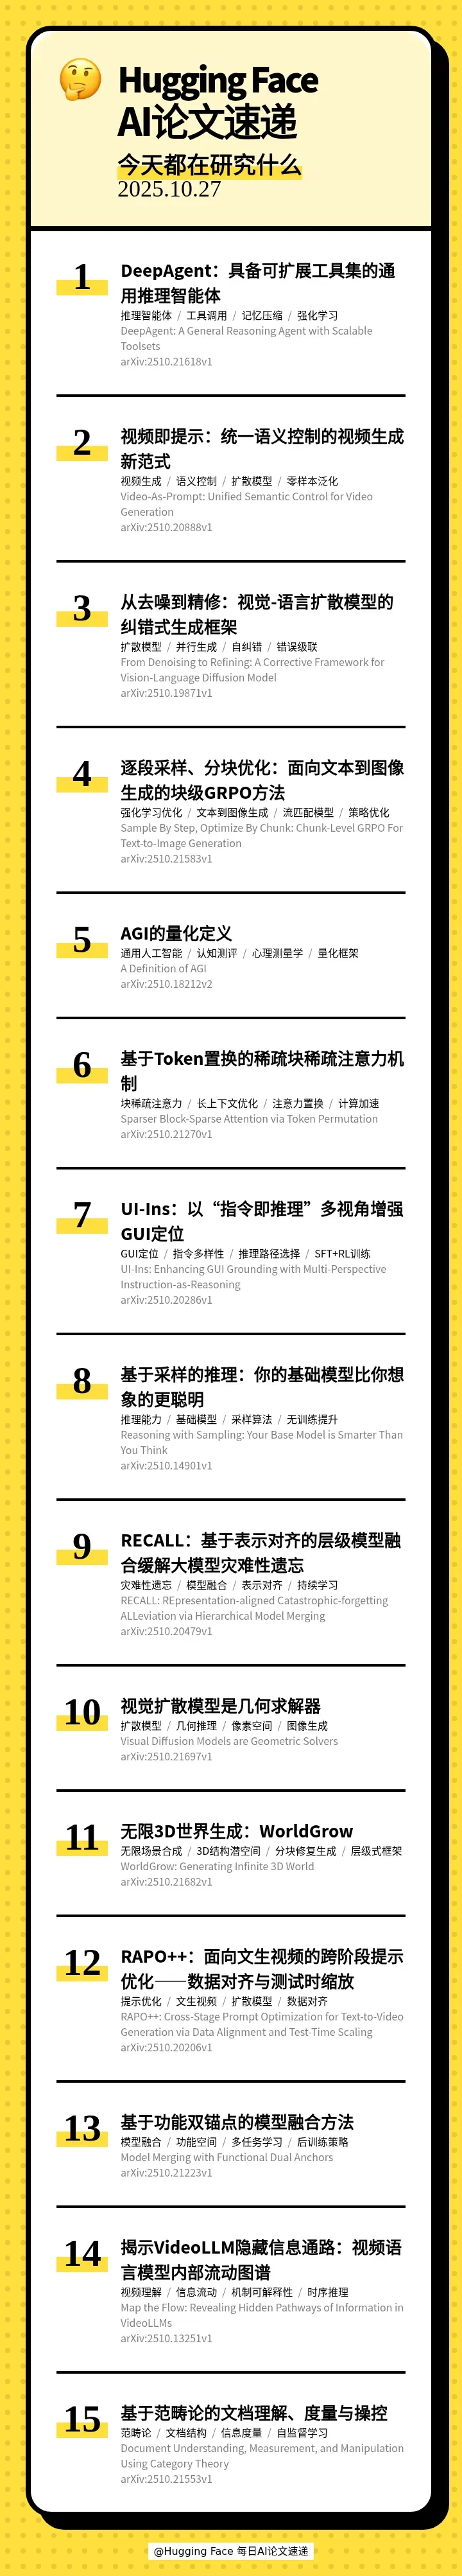
本期的 15 篇论文如下:
[] 🧠 DeepAgent: A General Reasoning Agent with Scalable Toolsets(DeepAgent:具备可扩展工具集的通用推理智能体)
[] 🎬 Video-As-Prompt: Unified Semantic Control for Video Generation(视频即提示:统一语义控制的视频生成新范式)
[] 🔧 From Denoising to Refining: A Corrective Framework for Vision-Language Diffusion Model(从去噪到精修:视觉-语言扩散模型的纠错式生成框架)
[] 🧩 Sample By Step, Optimize By Chunk: Chunk-Level GRPO For Text-to-Image Generation(逐段采样、分块优化:面向文本到图像生成的块级GRPO方法)
[] 🧠 A Definition of AGI(AGI的量化定义)
[] 🧩 Sparser Block-Sparse Attention via Token Permutation(基于Token置换的稀疏块稀疏注意力机制)
[] 🧭 UI-Ins: Enhancing GUI Grounding with Multi-Perspective Instruction-as-Reasoning(UI-Ins:以“指令即推理”多视角增强GUI定位)
[] 🧠 Reasoning with Sampling: Your Base Model is Smarter Than You Think(基于采样的推理:你的基础模型比你想象的更聪明)
[] 🧠 RECALL: REpresentation-aligned Catastrophic-forgetting ALLeviation via Hierarchical Model Merging(RECALL:基于表示对齐的层级模型融合缓解大模型灾难性遗忘)
[] 📐 Visual Diffusion Models are Geometric Solvers(视觉扩散模型是几何求解器)
[] 🌍 WorldGrow: Generating Infinite 3D World(无限3D世界生成:WorldGrow)
[] 🎬 RAPO++: Cross-Stage Prompt Optimization for Text-to-Video Generation via Data Alignment and Test-Time Scaling(RAPO++:面向文生视频的跨阶段提示优化——数据对齐与测试时缩放)
[] 🔗 Model Merging with Functional Dual Anchors(基于功能双锚点的模型融合方法)
[] 🧭 Map the Flow: Revealing Hidden Pathways of Information in VideoLLMs(揭示VideoLLM隐藏信息通路:视频语言模型内部流动图谱)
[] 📊 Document Understanding, Measurement, and Manipulation Using Category Theory(基于范畴论的文档理解、度量与操控)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 10 月 28 日 · 10 分钟
本期的 15 篇论文如下:
[] 🧠 DeepAgent: A General Reasoning Agent with Scalable Toolsets(DeepAgent:具备可扩展工具集的通用推理智能体)
[] 🎬 Video-As-Prompt: Unified Semantic Control for Video Generation(视频即提示:统一语义控制的视频生成新范式)
[] 🔧 From Denoising to Refining: A Corrective Framework for Vision-Language Diffusion Model(从去噪到精修:视觉-语言扩散模型的纠错式生成框架)
[] 🧩 Sample By Step, Optimize By Chunk: Chunk-Level GRPO For Text-to-Image Generation(逐段采样、分块优化:面向文本到图像生成的块级GRPO方法)
[] 🧠 A Definition of AGI(AGI的量化定义)
[] 🧩 Sparser Block-Sparse Attention via Token Permutation(基于Token置换的稀疏块稀疏注意力机制)
[] 🧭 UI-Ins: Enhancing GUI Grounding with Multi-Perspective Instruction-as-Reasoning(UI-Ins:以“指令即推理”多视角增强GUI定位)
[] 🧠 Reasoning with Sampling: Your Base Model is Smarter Than You Think(基于采样的推理:你的基础模型比你想象的更聪明)
[] 🧠 RECALL: REpresentation-aligned Catastrophic-forgetting ALLeviation via Hierarchical Model Merging(RECALL:基于表示对齐的层级模型融合缓解大模型灾难性遗忘)
[] 📐 Visual Diffusion Models are Geometric Solvers(视觉扩散模型是几何求解器)
[] 🌍 WorldGrow: Generating Infinite 3D World(无限3D世界生成:WorldGrow)
[] 🎬 RAPO++: Cross-Stage Prompt Optimization for Text-to-Video Generation via Data Alignment and Test-Time Scaling(RAPO++:面向文生视频的跨阶段提示优化——数据对齐与测试时缩放)
[] 🔗 Model Merging with Functional Dual Anchors(基于功能双锚点的模型融合方法)
[] 🧭 Map the Flow: Revealing Hidden Pathways of Information in VideoLLMs(揭示VideoLLM隐藏信息通路:视频语言模型内部流动图谱)
[] 📊 Document Understanding, Measurement, and Manipulation Using Category Theory(基于范畴论的文档理解、度量与操控)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟