H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

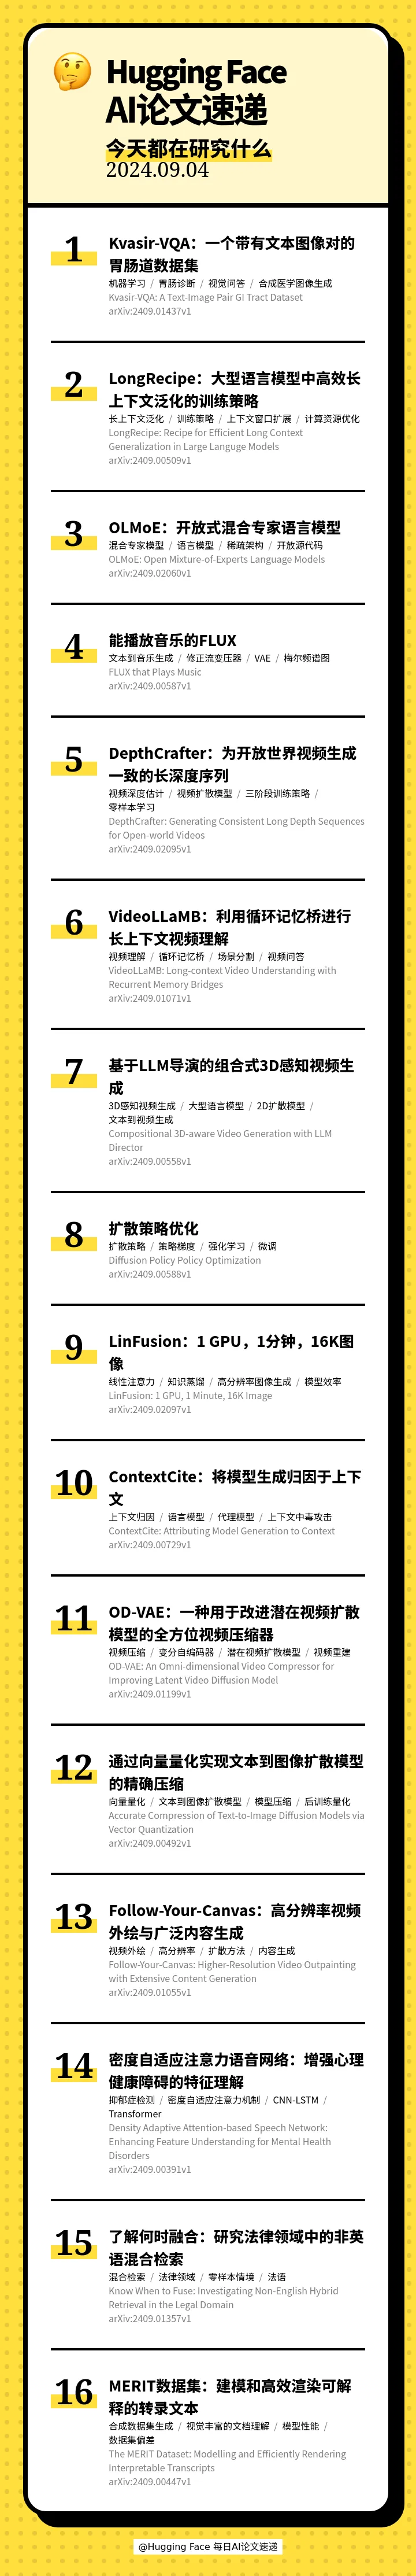
大家好,欢迎收听“Hugging Face 每日AI论文速递”。今天是2024年9月04日,我们将带您快速浏览16篇热门AI论文,涵盖数据集、语言模型、视频生成等多个领域。现在,让我们立即进入今天的论文速递。
[] 📊 Kvasir-VQA: A Text-Image Pair GI Tract Dataset(Kvasir-VQA:一个带有文本图像对的胃肠道数据集)
[] 📚 LongRecipe: Recipe for Efficient Long Context Generalization in Large Languge Models(LongRecipe:大型语言模型中高效长上下文泛化的训练策略)
[] 🧠 OLMoE: Open Mixture-of-Experts Language Models(OLMoE:开放式混合专家语言模型)
[] 🎶 FLUX that Plays Music(能播放音乐的FLUX)
[] 📹 DepthCrafter: Generating Consistent Long Depth Sequences for Open-world Videos(DepthCrafter:为开放世界视频生成一致的长深度序列)
[] 🎥 VideoLLaMB: Long-context Video Understanding with Recurrent Memory Bridges(VideoLLaMB:利用循环记忆桥进行长上下文视频理解)
[] 🎥 Compositional 3D-aware Video Generation with LLM Director(基于LLM导演的组合式3D感知视频生成)
[] 🤖 Diffusion Policy Policy Optimization(扩散策略优化)
[] 🚀 LinFusion: 1 GPU, 1 Minute, 16K Image(LinFusion:1 GPU,1分钟,16K图像)
[] 🔍 ContextCite: Attributing Model Generation to Context(ContextCite:将模型生成归因于上下文)
[] 📺 OD-VAE: An Omni-dimensional Video Compressor for Improving Latent Video Diffusion Model(OD-VAE:一种用于改进潜在视频扩散模型的全方位视频压缩器)
[] 📉 Accurate Compression of Text-to-Image Diffusion Models via Vector Quantization(通过向量量化实现文本到图像扩散模型的精确压缩)
[] 🎥 Follow-Your-Canvas: Higher-Resolution Video Outpainting with Extensive Content Generation(Follow-Your-Canvas:高分辨率视频外绘与广泛内容生成)
[] 🧠 Density Adaptive Attention-based Speech Network: Enhancing Feature Understanding for Mental Health Disorders(密度自适应注意力语音网络:增强心理健康障碍的特征理解)
[] 📚 Know When to Fuse: Investigating Non-English Hybrid Retrieval in the Legal Domain(了解何时融合:研究法律领域中的非英语混合检索)
[] 📚 The MERIT Dataset: Modelling and Efficiently Rendering Interpretable Transcripts(MERIT数据集:建模和高效渲染可解释的转录文本)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2024 年 9 月 5 日 · 11 分钟
大家好,欢迎收听“Hugging Face 每日AI论文速递”。今天是2024年9月04日,我们将带您快速浏览16篇热门AI论文,涵盖数据集、语言模型、视频生成等多个领域。现在,让我们立即进入今天的论文速递。
[] 📊 Kvasir-VQA: A Text-Image Pair GI Tract Dataset(Kvasir-VQA:一个带有文本图像对的胃肠道数据集)
[] 📚 LongRecipe: Recipe for Efficient Long Context Generalization in Large Languge Models(LongRecipe:大型语言模型中高效长上下文泛化的训练策略)
[] 🧠 OLMoE: Open Mixture-of-Experts Language Models(OLMoE:开放式混合专家语言模型)
[] 🎶 FLUX that Plays Music(能播放音乐的FLUX)
[] 📹 DepthCrafter: Generating Consistent Long Depth Sequences for Open-world Videos(DepthCrafter:为开放世界视频生成一致的长深度序列)
[] 🎥 VideoLLaMB: Long-context Video Understanding with Recurrent Memory Bridges(VideoLLaMB:利用循环记忆桥进行长上下文视频理解)
[] 🎥 Compositional 3D-aware Video Generation with LLM Director(基于LLM导演的组合式3D感知视频生成)
[] 🤖 Diffusion Policy Policy Optimization(扩散策略优化)
[] 🚀 LinFusion: 1 GPU, 1 Minute, 16K Image(LinFusion:1 GPU,1分钟,16K图像)
[] 🔍 ContextCite: Attributing Model Generation to Context(ContextCite:将模型生成归因于上下文)
[] 📺 OD-VAE: An Omni-dimensional Video Compressor for Improving Latent Video Diffusion Model(OD-VAE:一种用于改进潜在视频扩散模型的全方位视频压缩器)
[] 📉 Accurate Compression of Text-to-Image Diffusion Models via Vector Quantization(通过向量量化实现文本到图像扩散模型的精确压缩)
[] 🎥 Follow-Your-Canvas: Higher-Resolution Video Outpainting with Extensive Content Generation(Follow-Your-Canvas:高分辨率视频外绘与广泛内容生成)
[] 🧠 Density Adaptive Attention-based Speech Network: Enhancing Feature Understanding for Mental Health Disorders(密度自适应注意力语音网络:增强心理健康障碍的特征理解)
[] 📚 Know When to Fuse: Investigating Non-English Hybrid Retrieval in the Legal Domain(了解何时融合:研究法律领域中的非英语混合检索)
[] 📚 The MERIT Dataset: Modelling and Efficiently Rendering Interpretable Transcripts(MERIT数据集:建模和高效渲染可解释的转录文本)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟