H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
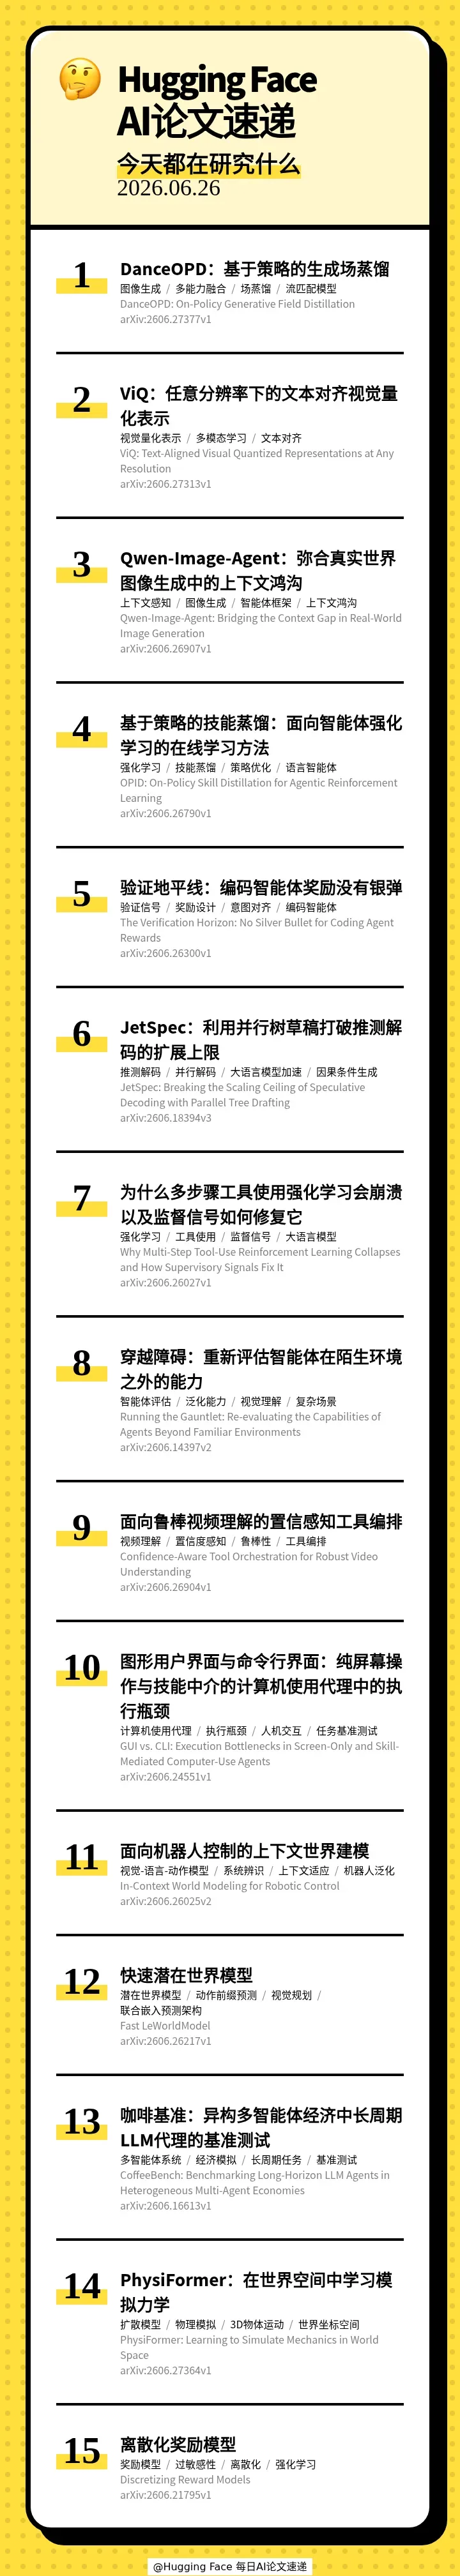
[] 💃 DanceOPD: On-Policy Generative Field Distillation(DanceOPD:基于策略的生成场蒸馏)
[] 🔍 ViQ: Text-Aligned Visual Quantized Representations at Any Resolution(ViQ:任意分辨率下的文本对齐视觉量化表示)
[] 🎨 Qwen-Image-Agent: Bridging the Context Gap in Real-World Image Generation(Qwen-Image-Agent:弥合真实世界图像生成中的上下文鸿沟)
[] 🤖 OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning(基于策略的技能蒸馏:面向智能体强化学习的在线学习方法)
[] 🔍 The Verification Horizon: No Silver Bullet for Coding Agent Rewards(验证地平线:编码智能体奖励没有银弹)
[] 🚀 JetSpec: Breaking the Scaling Ceiling of Speculative Decoding with Parallel Tree Drafting(JetSpec:利用并行树草稿打破推测解码的扩展上限)
[] 🛠 Why Multi-Step Tool-Use Reinforcement Learning Collapses and How Supervisory Signals Fix It(为什么多步骤工具使用强化学习会崩溃以及监督信号如何修复它)
[] 🧩 Running the Gauntlet: Re-evaluating the Capabilities of Agents Beyond Familiar Environments(穿越障碍:重新评估智能体在陌生环境之外的能力)
[] 🔍 Confidence-Aware Tool Orchestration for Robust Video Understanding(面向鲁棒视频理解的置信感知工具编排)
[] 🖥 GUI vs. CLI: Execution Bottlenecks in Screen-Only and Skill-Mediated Computer-Use Agents(图形用户界面与命令行界面:纯屏幕操作与技能中介的计算机使用代理中的执行瓶颈)
[] 🤖 In-Context World Modeling for Robotic Control(面向机器人控制的上下文世界建模)
[] 🚀 Fast LeWorldModel(快速潜在世界模型)
[] ☕ CoffeeBench: Benchmarking Long-Horizon LLM Agents in Heterogeneous Multi-Agent Economies(咖啡基准:异构多智能体经济中长周期LLM代理的基准测试)
[] 🧊 PhysiFormer: Learning to Simulate Mechanics in World Space(PhysiFormer:在世界空间中学习模拟力学)
[] 🎲 Discretizing Reward Models(离散化奖励模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 6 月 27 日 · 15 分钟
【赞助商】
OpenClaw快报
每天五分钟,听听 OpenClaw 快报,带你了解最新动态和业内讨论
传送门 https://www.xiaoyuzhoufm.com/podcast/6a1732a2dffa135d0ab5ef43
【目录】
本期的 15 篇论文如下:
[] 💃 DanceOPD: On-Policy Generative Field Distillation(DanceOPD:基于策略的生成场蒸馏)
[] 🔍 ViQ: Text-Aligned Visual Quantized Representations at Any Resolution(ViQ:任意分辨率下的文本对齐视觉量化表示)
[] 🎨 Qwen-Image-Agent: Bridging the Context Gap in Real-World Image Generation(Qwen-Image-Agent:弥合真实世界图像生成中的上下文鸿沟)
[] 🤖 OPID: On-Policy Skill Distillation for Agentic Reinforcement Learning(基于策略的技能蒸馏:面向智能体强化学习的在线学习方法)
[] 🔍 The Verification Horizon: No Silver Bullet for Coding Agent Rewards(验证地平线:编码智能体奖励没有银弹)
[] 🚀 JetSpec: Breaking the Scaling Ceiling of Speculative Decoding with Parallel Tree Drafting(JetSpec:利用并行树草稿打破推测解码的扩展上限)
[] 🛠 Why Multi-Step Tool-Use Reinforcement Learning Collapses and How Supervisory Signals Fix It(为什么多步骤工具使用强化学习会崩溃以及监督信号如何修复它)
[] 🧩 Running the Gauntlet: Re-evaluating the Capabilities of Agents Beyond Familiar Environments(穿越障碍:重新评估智能体在陌生环境之外的能力)
[] 🔍 Confidence-Aware Tool Orchestration for Robust Video Understanding(面向鲁棒视频理解的置信感知工具编排)
[] 🖥 GUI vs. CLI: Execution Bottlenecks in Screen-Only and Skill-Mediated Computer-Use Agents(图形用户界面与命令行界面:纯屏幕操作与技能中介的计算机使用代理中的执行瓶颈)
[] 🤖 In-Context World Modeling for Robotic Control(面向机器人控制的上下文世界建模)
[] 🚀 Fast LeWorldModel(快速潜在世界模型)
[] ☕ CoffeeBench: Benchmarking Long-Horizon LLM Agents in Heterogeneous Multi-Agent Economies(咖啡基准:异构多智能体经济中长周期LLM代理的基准测试)
[] 🧊 PhysiFormer: Learning to Simulate Mechanics in World Space(PhysiFormer:在世界空间中学习模拟力学)
[] 🎲 Discretizing Reward Models(离散化奖励模型)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟