H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

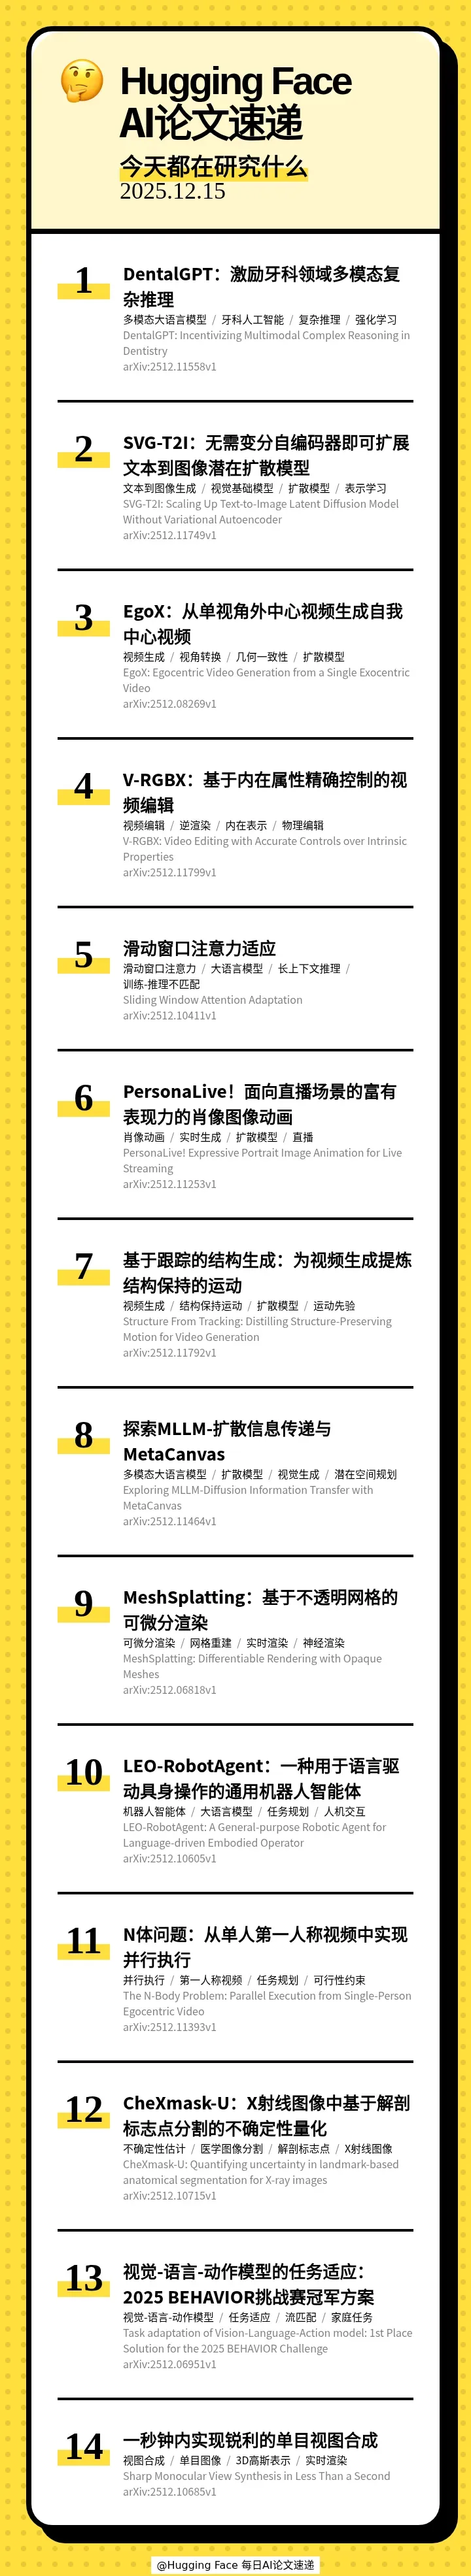
本期的 14 篇论文如下:
[] 🦷 DentalGPT: Incentivizing Multimodal Complex Reasoning in Dentistry(DentalGPT:激励牙科领域多模态复杂推理)
[] 🎨 SVG-T2I: Scaling Up Text-to-Image Latent Diffusion Model Without Variational Autoencoder(SVG-T2I:无需变分自编码器即可扩展文本到图像潜在扩散模型)
[] 🎥 EgoX: Egocentric Video Generation from a Single Exocentric Video(EgoX:从单视角外中心视频生成自我中心视频)
[] 🎬 V-RGBX: Video Editing with Accurate Controls over Intrinsic Properties(V-RGBX:基于内在属性精确控制的视频编辑)
[] 🔍 Sliding Window Attention Adaptation(滑动窗口注意力适应)
[] 🎬 PersonaLive! Expressive Portrait Image Animation for Live Streaming(PersonaLive!面向直播场景的富有表现力的肖像图像动画)
[] 🎬 Structure From Tracking: Distilling Structure-Preserving Motion for Video Generation(基于跟踪的结构生成:为视频生成提炼结构保持的运动)
[] 🎨 Exploring MLLM-Diffusion Information Transfer with MetaCanvas(探索MLLM-扩散信息传递与MetaCanvas)
[] 🔄 MeshSplatting: Differentiable Rendering with Opaque Meshes(MeshSplatting:基于不透明网格的可微分渲染)
[] 🤖 LEO-RobotAgent: A General-purpose Robotic Agent for Language-driven Embodied Operator(LEO-RobotAgent:一种用于语言驱动具身操作的通用机器人智能体)
[] ⚡ The N-Body Problem: Parallel Execution from Single-Person Egocentric Video(N体问题:从单人第一人称视频中实现并行执行)
[] 🧬 CheXmask-U: Quantifying uncertainty in landmark-based anatomical segmentation for X-ray images(CheXmask-U:X射线图像中基于解剖标志点分割的不确定性量化)
[] 🏆 Task adaptation of Vision-Language-Action model: 1st Place Solution for the 2025 BEHAVIOR Challenge(视觉-语言-动作模型的任务适应:2025 BEHAVIOR挑战赛冠军方案)
[] 🚀 Sharp Monocular View Synthesis in Less Than a Second(一秒钟内实现锐利的单目视图合成)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 12 月 16 日 · 9 分钟
本期的 14 篇论文如下:
[] 🦷 DentalGPT: Incentivizing Multimodal Complex Reasoning in Dentistry(DentalGPT:激励牙科领域多模态复杂推理)
[] 🎨 SVG-T2I: Scaling Up Text-to-Image Latent Diffusion Model Without Variational Autoencoder(SVG-T2I:无需变分自编码器即可扩展文本到图像潜在扩散模型)
[] 🎥 EgoX: Egocentric Video Generation from a Single Exocentric Video(EgoX:从单视角外中心视频生成自我中心视频)
[] 🎬 V-RGBX: Video Editing with Accurate Controls over Intrinsic Properties(V-RGBX:基于内在属性精确控制的视频编辑)
[] 🔍 Sliding Window Attention Adaptation(滑动窗口注意力适应)
[] 🎬 PersonaLive! Expressive Portrait Image Animation for Live Streaming(PersonaLive!面向直播场景的富有表现力的肖像图像动画)
[] 🎬 Structure From Tracking: Distilling Structure-Preserving Motion for Video Generation(基于跟踪的结构生成:为视频生成提炼结构保持的运动)
[] 🎨 Exploring MLLM-Diffusion Information Transfer with MetaCanvas(探索MLLM-扩散信息传递与MetaCanvas)
[] 🔄 MeshSplatting: Differentiable Rendering with Opaque Meshes(MeshSplatting:基于不透明网格的可微分渲染)
[] 🤖 LEO-RobotAgent: A General-purpose Robotic Agent for Language-driven Embodied Operator(LEO-RobotAgent:一种用于语言驱动具身操作的通用机器人智能体)
[] ⚡ The N-Body Problem: Parallel Execution from Single-Person Egocentric Video(N体问题:从单人第一人称视频中实现并行执行)
[] 🧬 CheXmask-U: Quantifying uncertainty in landmark-based anatomical segmentation for X-ray images(CheXmask-U:X射线图像中基于解剖标志点分割的不确定性量化)
[] 🏆 Task adaptation of Vision-Language-Action model: 1st Place Solution for the 2025 BEHAVIOR Challenge(视觉-语言-动作模型的任务适应:2025 BEHAVIOR挑战赛冠军方案)
[] 🚀 Sharp Monocular View Synthesis in Less Than a Second(一秒钟内实现锐利的单目视图合成)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟