H
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟

本期的 15 篇论文如下:
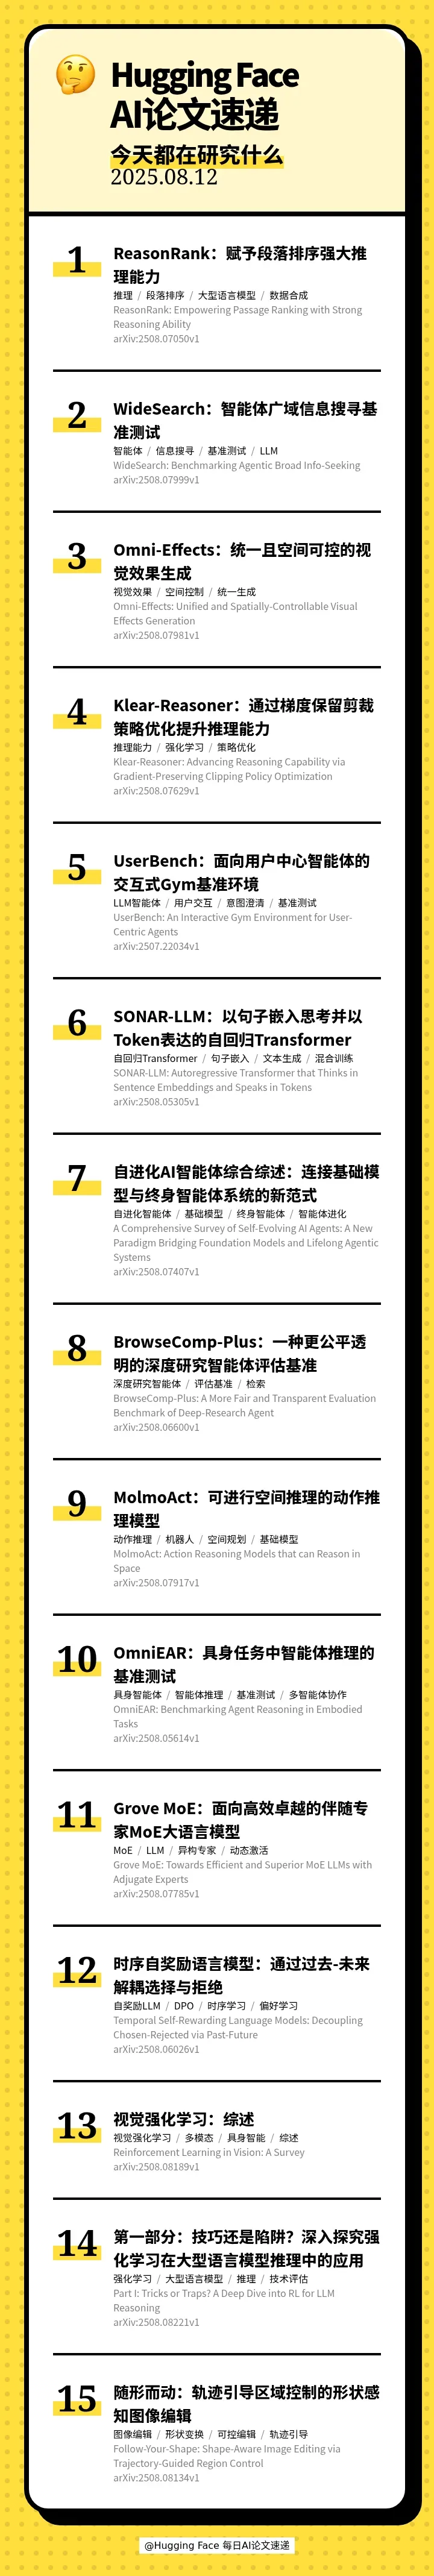
[] 🧠 ReasonRank: Empowering Passage Ranking with Strong Reasoning Ability(ReasonRank:赋予段落排序强大推理能力)
[] 🔍 WideSearch: Benchmarking Agentic Broad Info-Seeking(WideSearch:智能体广域信息搜寻基准测试)
[] ✨ Omni-Effects: Unified and Spatially-Controllable Visual Effects Generation(Omni-Effects:统一且空间可控的视觉效果生成)
[] 🧠 Klear-Reasoner: Advancing Reasoning Capability via Gradient-Preserving Clipping Policy Optimization(Klear-Reasoner:通过梯度保留剪裁策略优化提升推理能力)
[] 💬 UserBench: An Interactive Gym Environment for User-Centric Agents(UserBench:面向用户中心智能体的交互式Gym基准环境)
[] 💡 SONAR-LLM: Autoregressive Transformer that Thinks in Sentence Embeddings and Speaks in Tokens(SONAR-LLM:以句子嵌入思考并以Token表达的自回归Transformer)
[] 🌱 A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems(自进化AI智能体综合综述:连接基础模型与终身智能体系统的新范式)
[] 🔬 BrowseComp-Plus: A More Fair and Transparent Evaluation Benchmark of Deep-Research Agent(BrowseComp-Plus:一种更公平透明的深度研究智能体评估基准)
[] 🤖 MolmoAct: Action Reasoning Models that can Reason in Space(MolmoAct:可进行空间推理的动作推理模型)
[] 🤖 OmniEAR: Benchmarking Agent Reasoning in Embodied Tasks(OmniEAR:具身任务中智能体推理的基准测试)
[] 💡 Grove MoE: Towards Efficient and Superior MoE LLMs with Adjugate Experts(Grove MoE:面向高效卓越的伴随专家MoE大语言模型)
[] ⏳ Temporal Self-Rewarding Language Models: Decoupling Chosen-Rejected via Past-Future(时序自奖励语言模型:通过过去-未来解耦选择与拒绝)
[] 🗺 Reinforcement Learning in Vision: A Survey(视觉强化学习:综述)
[] 🔍 Part I: Tricks or Traps? A Deep Dive into RL for LLM Reasoning(第一部分:技巧还是陷阱?深入探究强化学习在大型语言模型推理中的应用)
[] 🖌 Follow-Your-Shape: Shape-Aware Image Editing via Trajectory-Guided Region Control(随形而动:轨迹引导区域控制的形状感知图像编辑)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟
【月末特辑】10月最火AI论文 | 把经验变成预见;让音画同步生成
11 月 7 日 · 13 分钟

HuggingFace 每日AI论文速递 · 2025 年 8 月 13 日 · 7 分钟
本期的 15 篇论文如下:
[] 🧠 ReasonRank: Empowering Passage Ranking with Strong Reasoning Ability(ReasonRank:赋予段落排序强大推理能力)
[] 🔍 WideSearch: Benchmarking Agentic Broad Info-Seeking(WideSearch:智能体广域信息搜寻基准测试)
[] ✨ Omni-Effects: Unified and Spatially-Controllable Visual Effects Generation(Omni-Effects:统一且空间可控的视觉效果生成)
[] 🧠 Klear-Reasoner: Advancing Reasoning Capability via Gradient-Preserving Clipping Policy Optimization(Klear-Reasoner:通过梯度保留剪裁策略优化提升推理能力)
[] 💬 UserBench: An Interactive Gym Environment for User-Centric Agents(UserBench:面向用户中心智能体的交互式Gym基准环境)
[] 💡 SONAR-LLM: Autoregressive Transformer that Thinks in Sentence Embeddings and Speaks in Tokens(SONAR-LLM:以句子嵌入思考并以Token表达的自回归Transformer)
[] 🌱 A Comprehensive Survey of Self-Evolving AI Agents: A New Paradigm Bridging Foundation Models and Lifelong Agentic Systems(自进化AI智能体综合综述:连接基础模型与终身智能体系统的新范式)
[] 🔬 BrowseComp-Plus: A More Fair and Transparent Evaluation Benchmark of Deep-Research Agent(BrowseComp-Plus:一种更公平透明的深度研究智能体评估基准)
[] 🤖 MolmoAct: Action Reasoning Models that can Reason in Space(MolmoAct:可进行空间推理的动作推理模型)
[] 🤖 OmniEAR: Benchmarking Agent Reasoning in Embodied Tasks(OmniEAR:具身任务中智能体推理的基准测试)
[] 💡 Grove MoE: Towards Efficient and Superior MoE LLMs with Adjugate Experts(Grove MoE:面向高效卓越的伴随专家MoE大语言模型)
[] ⏳ Temporal Self-Rewarding Language Models: Decoupling Chosen-Rejected via Past-Future(时序自奖励语言模型:通过过去-未来解耦选择与拒绝)
[] 🗺 Reinforcement Learning in Vision: A Survey(视觉强化学习:综述)
[] 🔍 Part I: Tricks or Traps? A Deep Dive into RL for LLM Reasoning(第一部分:技巧还是陷阱?深入探究强化学习在大型语言模型推理中的应用)
[] 🖌 Follow-Your-Shape: Shape-Aware Image Editing via Trajectory-Guided Region Control(随形而动:轨迹引导区域控制的形状感知图像编辑)
【关注我们】
您还可以在以下平台找到我们,获得播客内容以外更多信息
小红书: AI速递
说明里标出的时间点,点一下跳过去

面向中文AI从业者与爱好者的每日AI论文速递,工作日高密度速览前沿论文,月末以月度热门论文特辑补充,形成每日速递加月末特…
已收录 739 期 · 最近更新 11 月 10 日
https://feed.xyzfm.space/7jtt3j3lbbra复制内容版权归创作者,声湃按创作者开放的 RSS 收录。了解收录与 RSS →
2026.11.09 | 高斯间距校准跨场景重建;参数先验加速多教师蒸馏
11 月 10 日 · 11 分钟
【周末特辑】11月第2周最火AI论文 | 图形智能体的设计空间;错峰去噪生成视频
11 月 8 日 · 11 分钟
2026.11.06 | 视觉规划整块解码;借兄弟框架练智能体
11 月 7 日 · 9 分钟